Retrieval augmented generation is a framework that determines which content AI tools retrieve and cite before generating an answer.
You need to understand RAG because it’s one of the ways ChatGPT, AI Mode and other AI search engines choose which pages get included in its answer.
This guide explains how RAG works (in plain English), what makes content more likely to be retrieved, and how to measure your visibility in AI systems that use RAG with Ahrefs Brand Radar.
Retrieval augmented generation (RAG) is a technique where an LLM queries an index—like a search engine, knowledge base, or vector database—to find additional, contextually relevant information for its response—rather than just defaulting to what it learned during training.
Large language models are trained on huge datasets, but that training has a cutoff date.
Ask an AI model what happened last week, or what’s in your live production database, and you’re asking it to work from memory with no reference material in front of it.
When you query an AI model on information it doesn’t yet have, that’s when it’s most likely to go rogue and start telling you that poison is good for you…
This is otherwise known as an AI “hallucination”.
RAG gives AI models access to the correct, up-to-date material to avoid this fate.
With RAG, LLMs are either supplementing or overriding their internal knowledge—known as their “parametric memory”—in an attempt to give a more reliable answer.
This process is also sometimes known as “grounding”; anchoring the response to specific sources so the model isn’t just freestyling from its training data.
Most AI tools use both RAG and trained knowledge in tandem.
Getting into the base model’s knowledge means being part of its training data, and that isn’t something you can easily control.
But getting into the retrieval results is, in many ways, an extension of SEO.
Every RAG-powered AI answer follows three steps: search, retrieve, generate.
To understand the details of what likely occurs at each stage, here’s what we know about how ChatGPT retrieves its sources.
Before anything gets retrieved, the AI will decide whether it even needs to enrich its knowledge with outside data.
Simple fact-finding queries like “What is a VPN?” can usually be fielded by the core model based on its existing training knowledge. No retrieval needed.
In ChatGPT’s case, a smaller classifier model (part of the “sonicberry” system according to David McSweeney, who put in the work to find out just how ChatGPT retrieves sources) will run first, assigning probability scores to determine whether a query needs: no search, a simple search, or a complex multi-step search.
Other AI tools will handle this step differently, but they all share the same underlying logic: not every query triggers a search.
Whenever someone asks ChatGPT a question that requires more context, it expands that query into multiple related queries, then sends them to an external search index like Bing or Google to collect results.
Once a selection of pages are collected, on-page SEO factors like the title, meta description/summary, and URL determine which page gets read in full, according to research by AI Expert Dan Petrovic.
From there, he discovered that sources are shortlisted for scraping based on “relevance, authority, recency, and diversity of perspective”.
Before it can be fully retrieved and served in the response, the scraped web content gets broken into smaller pieces called chunks.
Think of chunking like tearing a book into individual chapters. The system breaks the page into pieces, then asks which piece best answers the question.
ChatGPT converts the search query and each chunk into a numerical representation of meaning, known as an embedding, then measures their cosine similarity—a score of how semantically close they are.
The simplest way to picture this: imagine a giant map where similar ideas sit close together and unrelated ideas are far apart. On this map, “dog” and “puppy” would be near each other. “Dog” and “skateboard” would be on opposite ends.
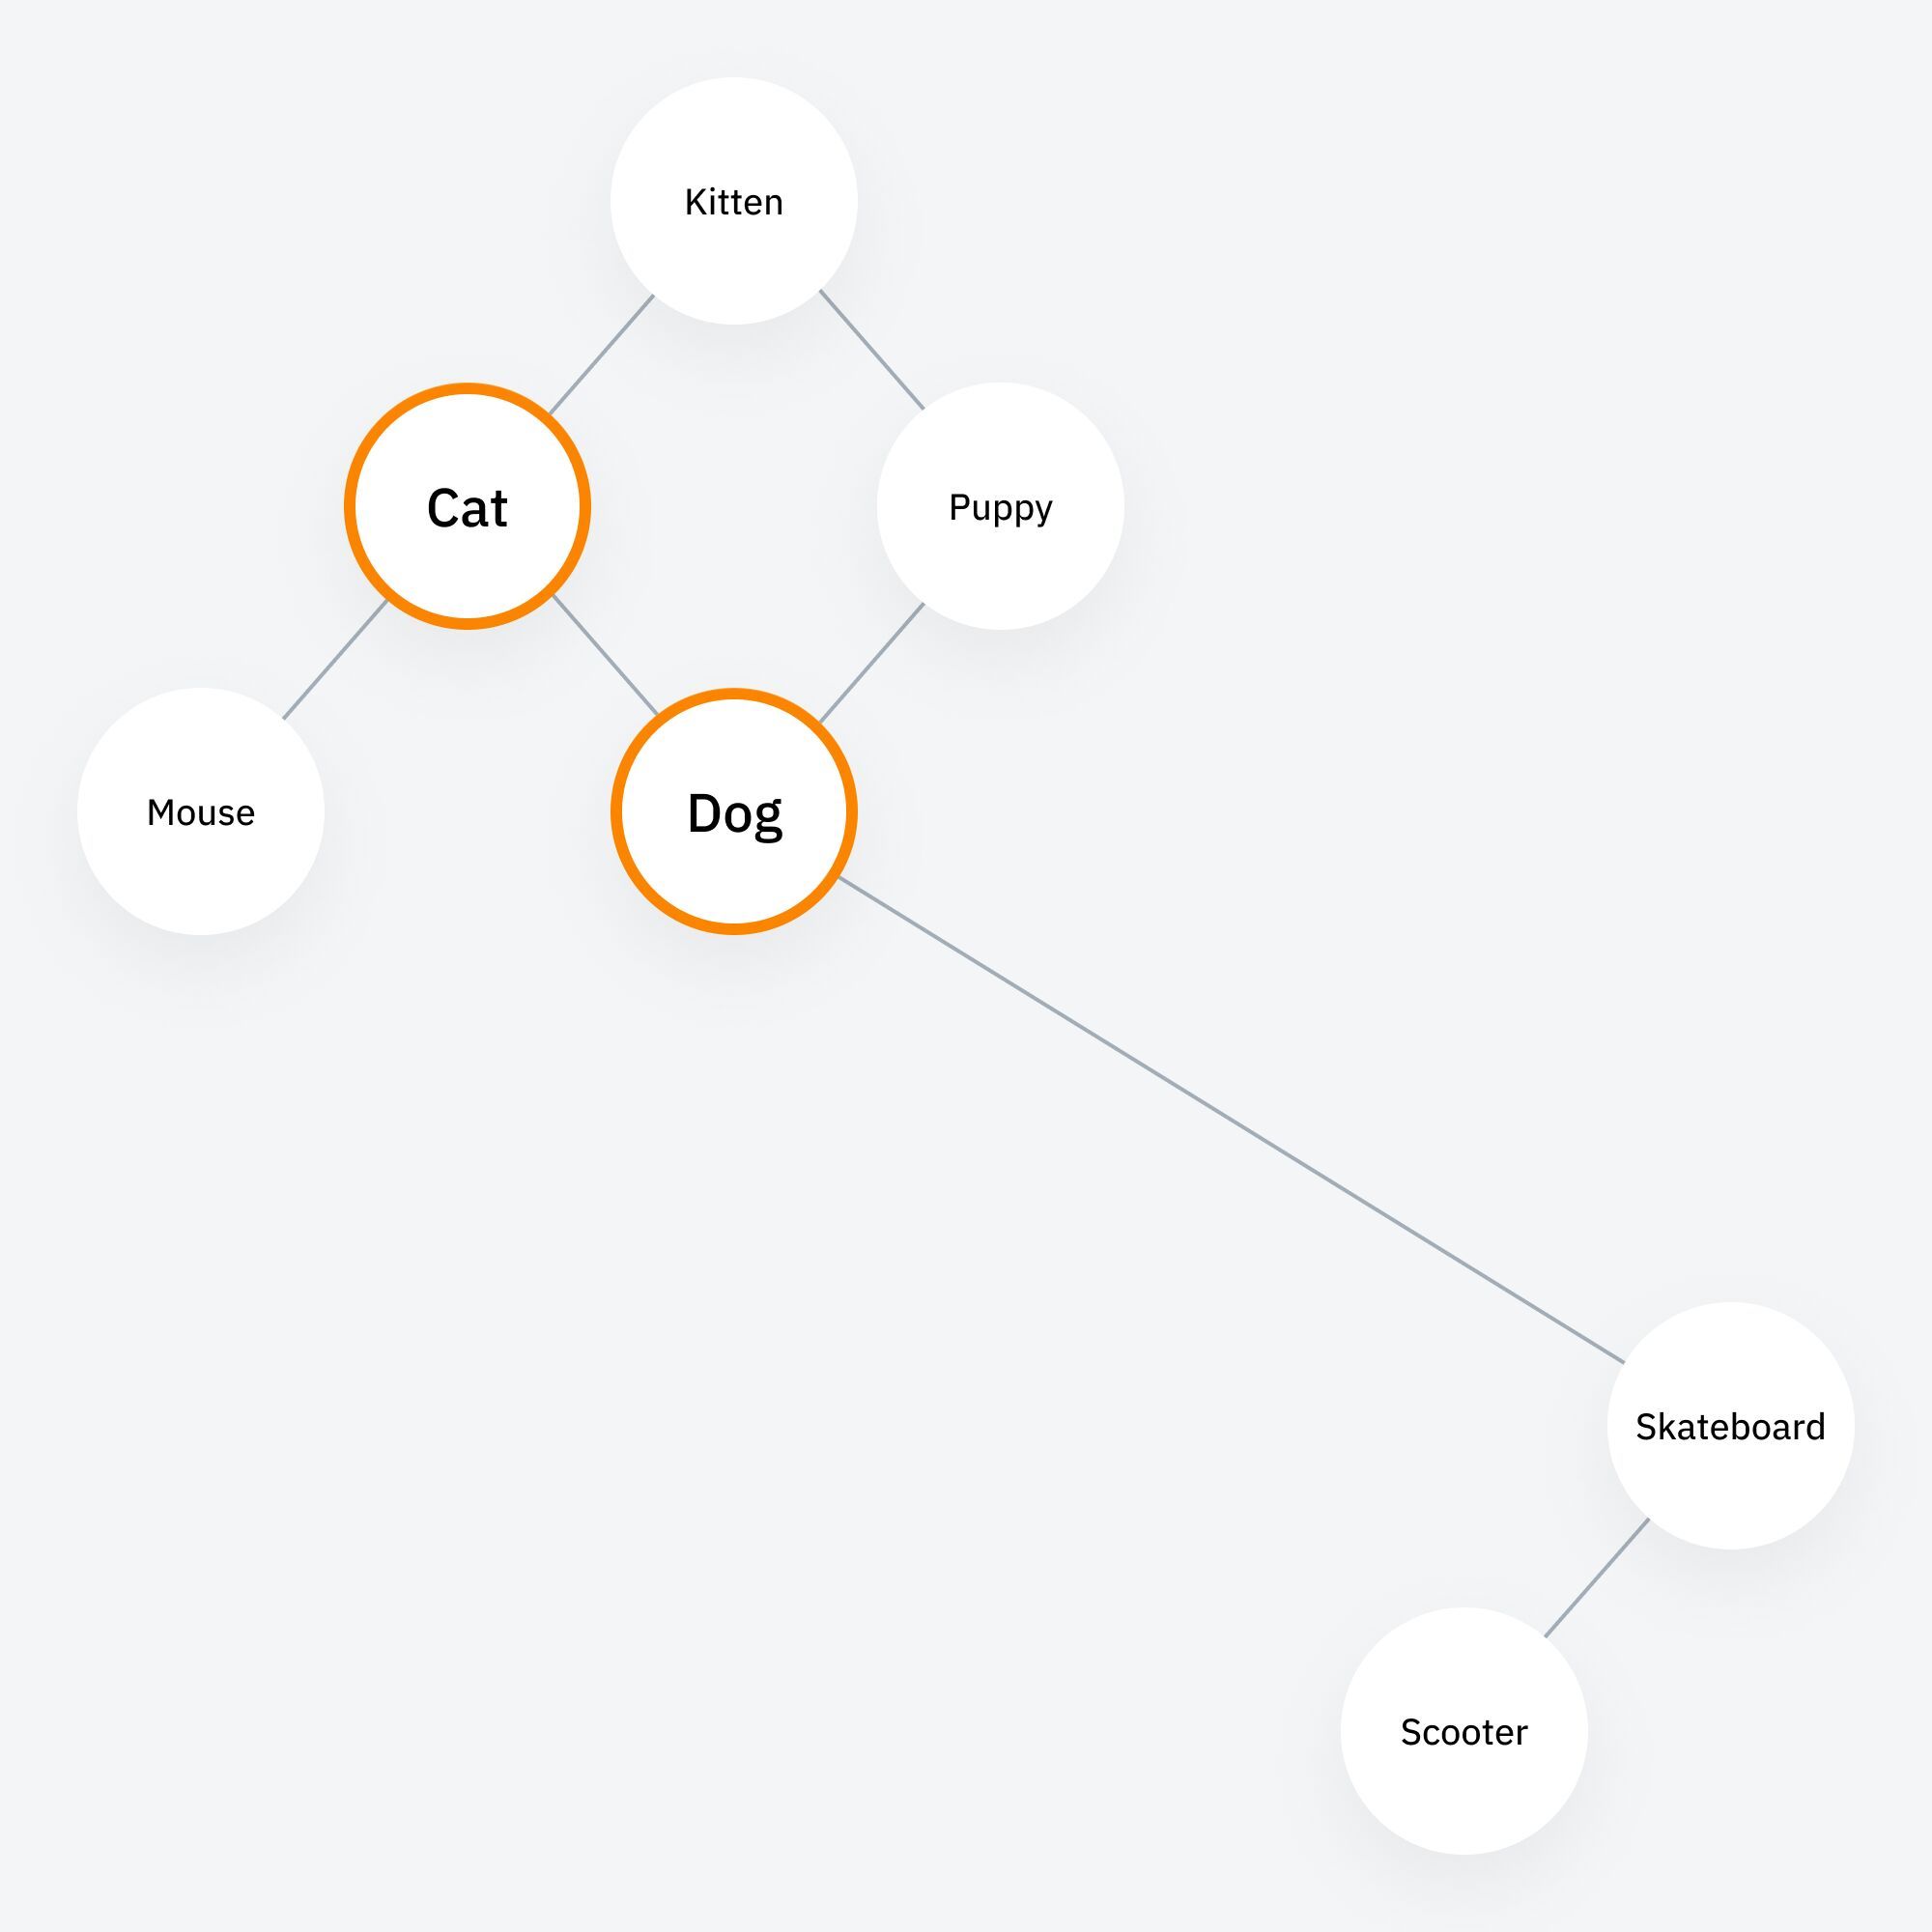
Embeddings are like GPS coordinates on that map—every piece of text gets assigned coordinates based on its meaning.
Cosine similarity is the measure of how close together two sets of coordinates are.
The AI retrieves the chunks whose coordinates are closest to the fan-out query’s coordinates, and the closest match wins.
This is why specific, clear language helps retrieval—it’s easier to map to the correct vector “coordinate”.
Step 3: Retrieved content loads into the AI’s working memory—briefly
The matching chunks are loaded into the AI’s context window—its short-term working memory—alongside the user’s original question.
It synthesizes an answer using both, then it deletes the chunks.
Dan Petrovic tested this directly: he asked an AI model to retrieve information on a well-known person, then in a follow-up message asked it to recall a specific snippet from its sources. It couldn’t.
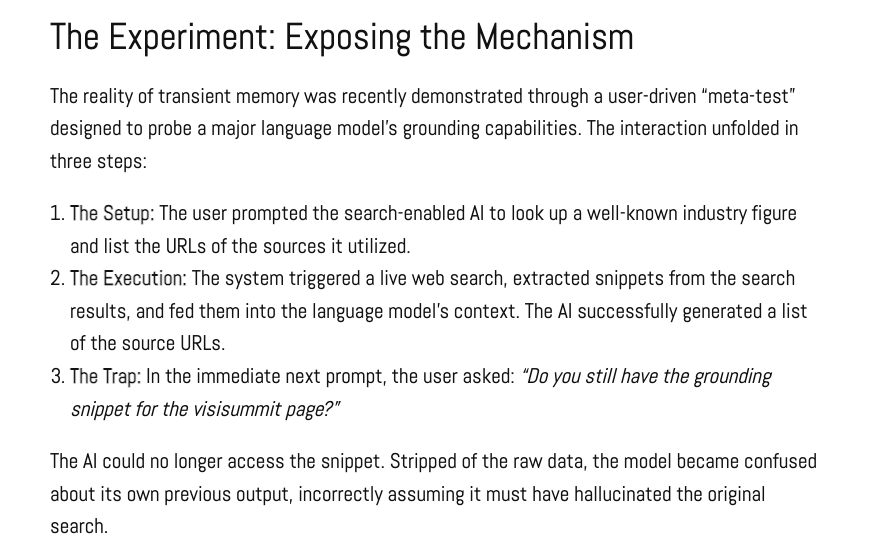
The raw content is “purged” the moment a response is generated.
Optimizing for retrieval isn’t wrong. In systems that rely heavily on live search for commercial queries, it can absolutely influence what gets surfaced. But assuming retrieval visibility is the same as foundational model weighting is where the strategy breaks. One takes weeks. The other is the slow work of entity coherence—how consistently and clearly your brand is understood across the broader web—and it takes years.”
Rather than searching your exact words, it breaks your question into multiple related sub-queries, runs each one separately, and pulls sources from the combined results.
Say someone searches “What will happen if I swap out regular flour for wholemeal flour in a lemon drizzle” in Google, the underlying AI search model wouldn’t just search that phrase, it might also look up:
- Best flour for lemon drizzle
- Baking with wholemeal flour tips
- How does wholemeal flour affect cake density?
Before synthesizing an answer.
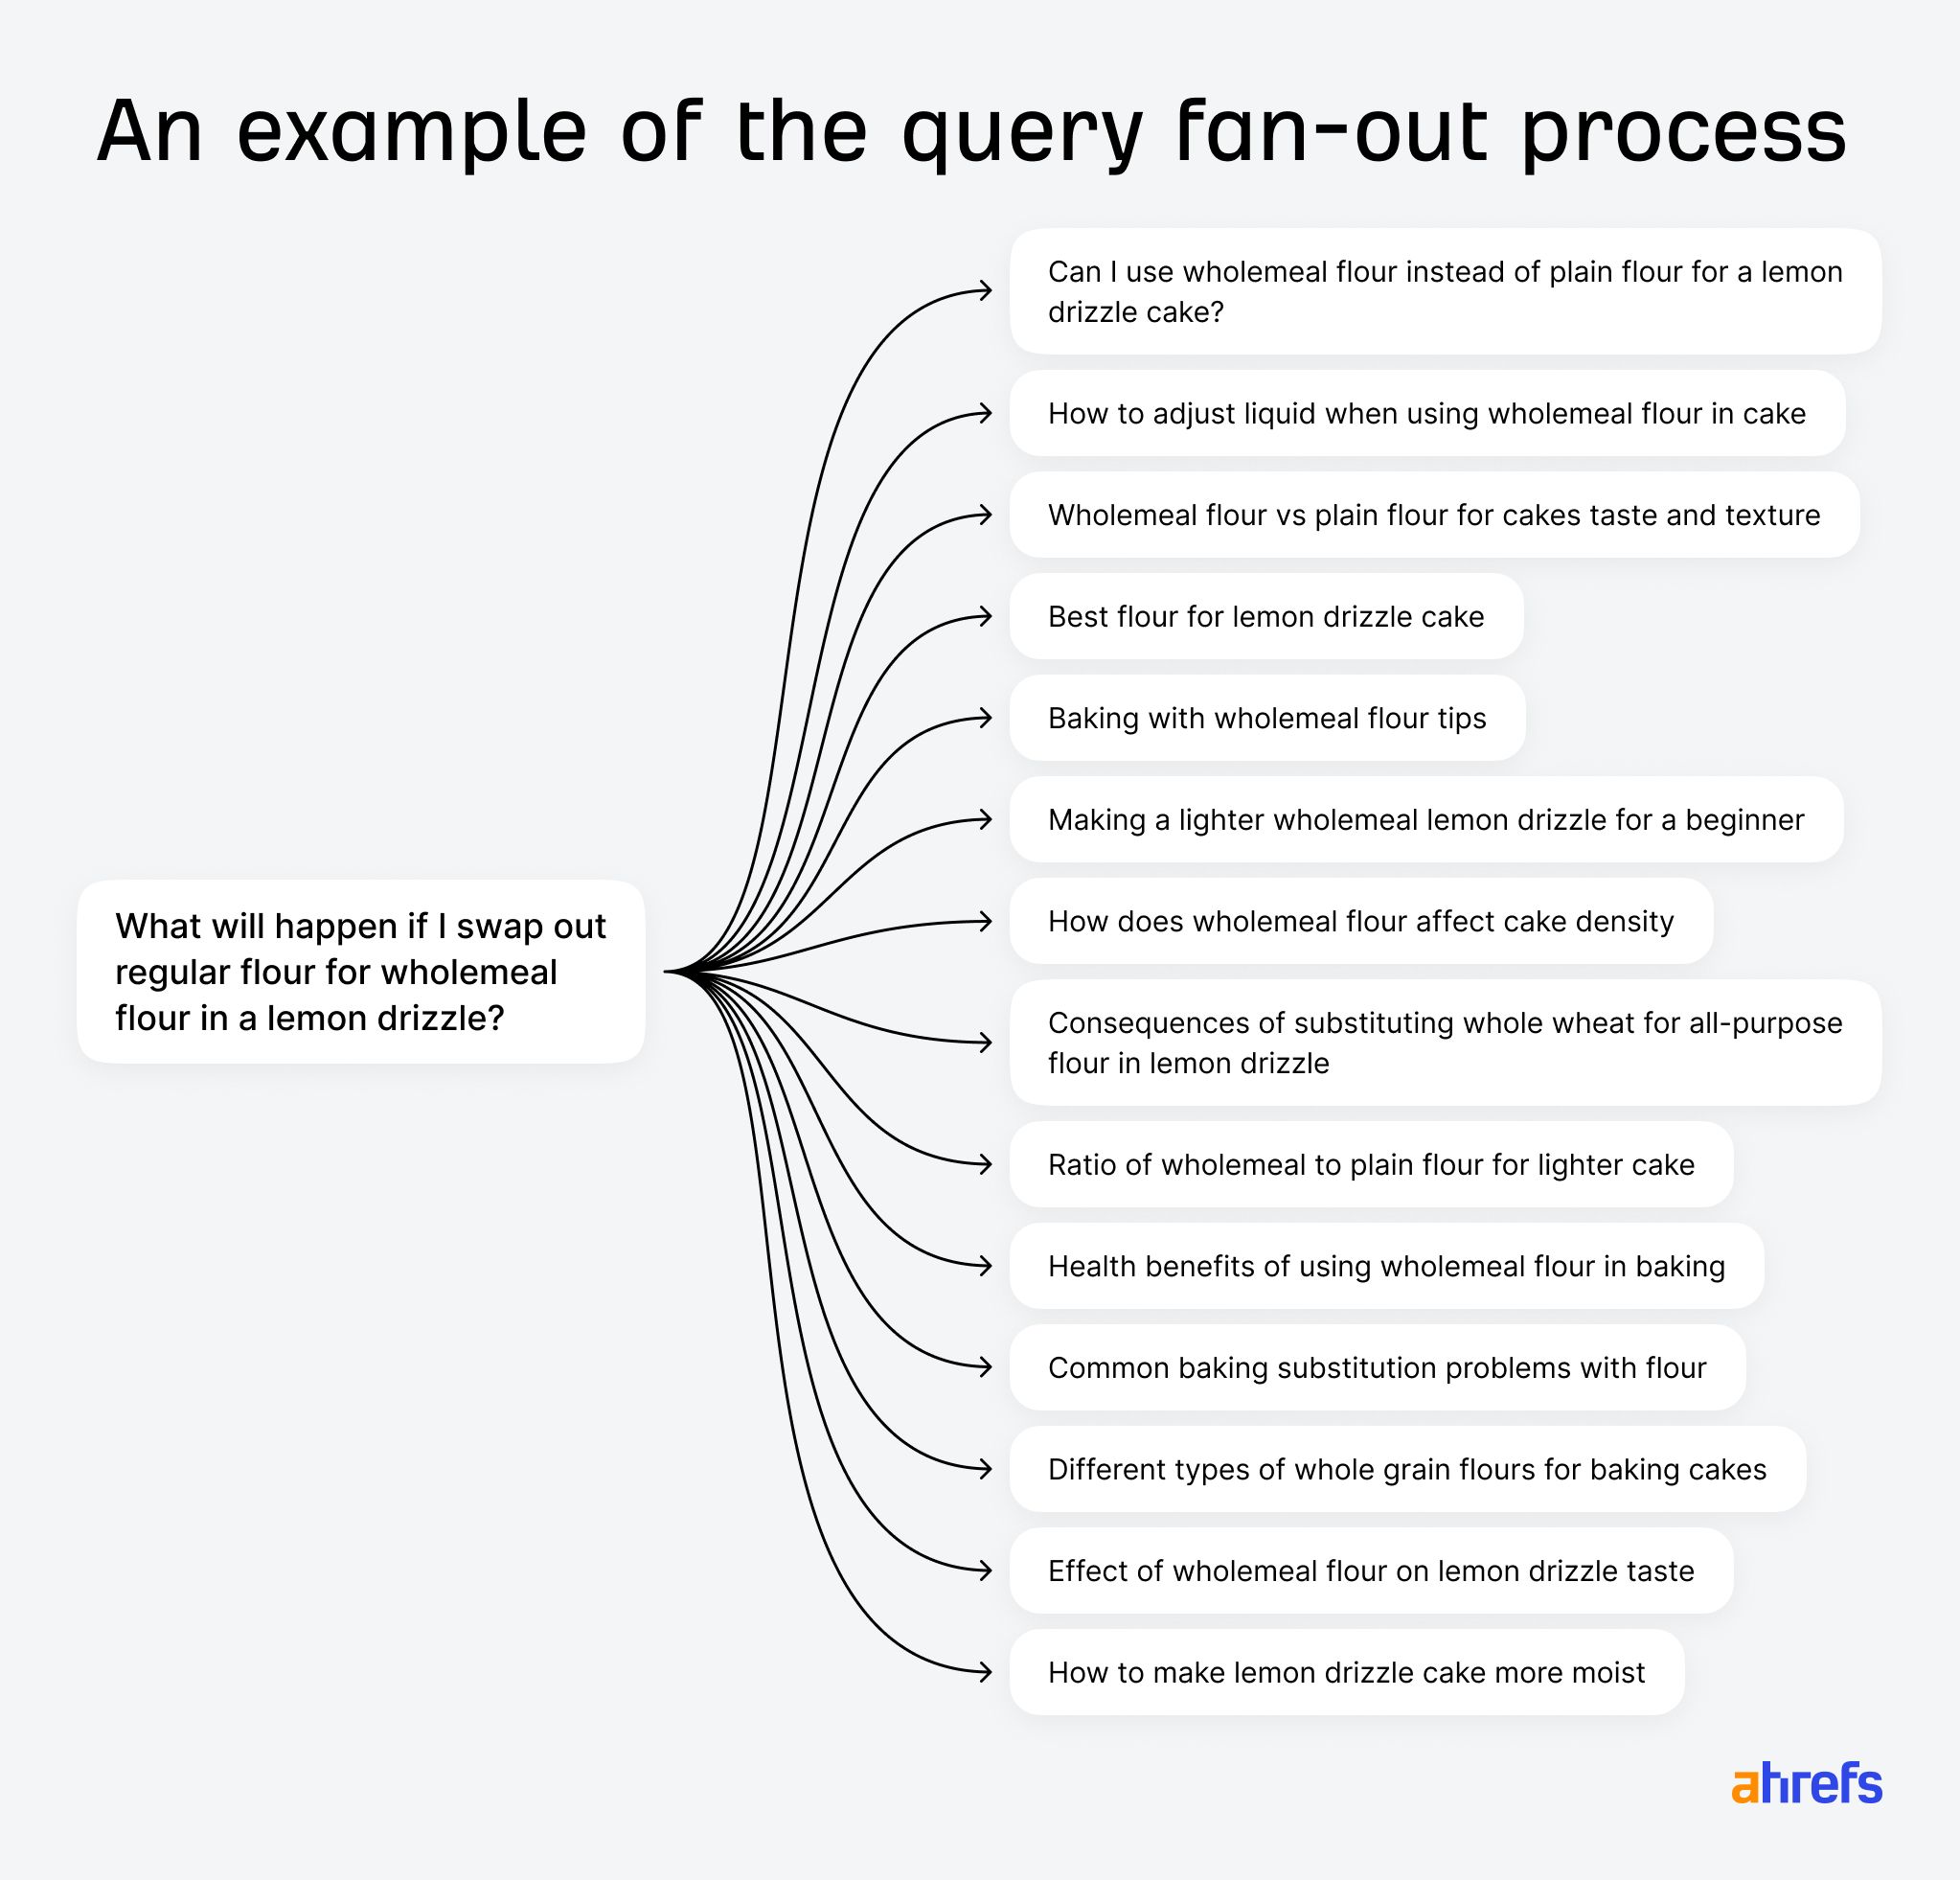
AI does the same thing automatically on most complex queries.
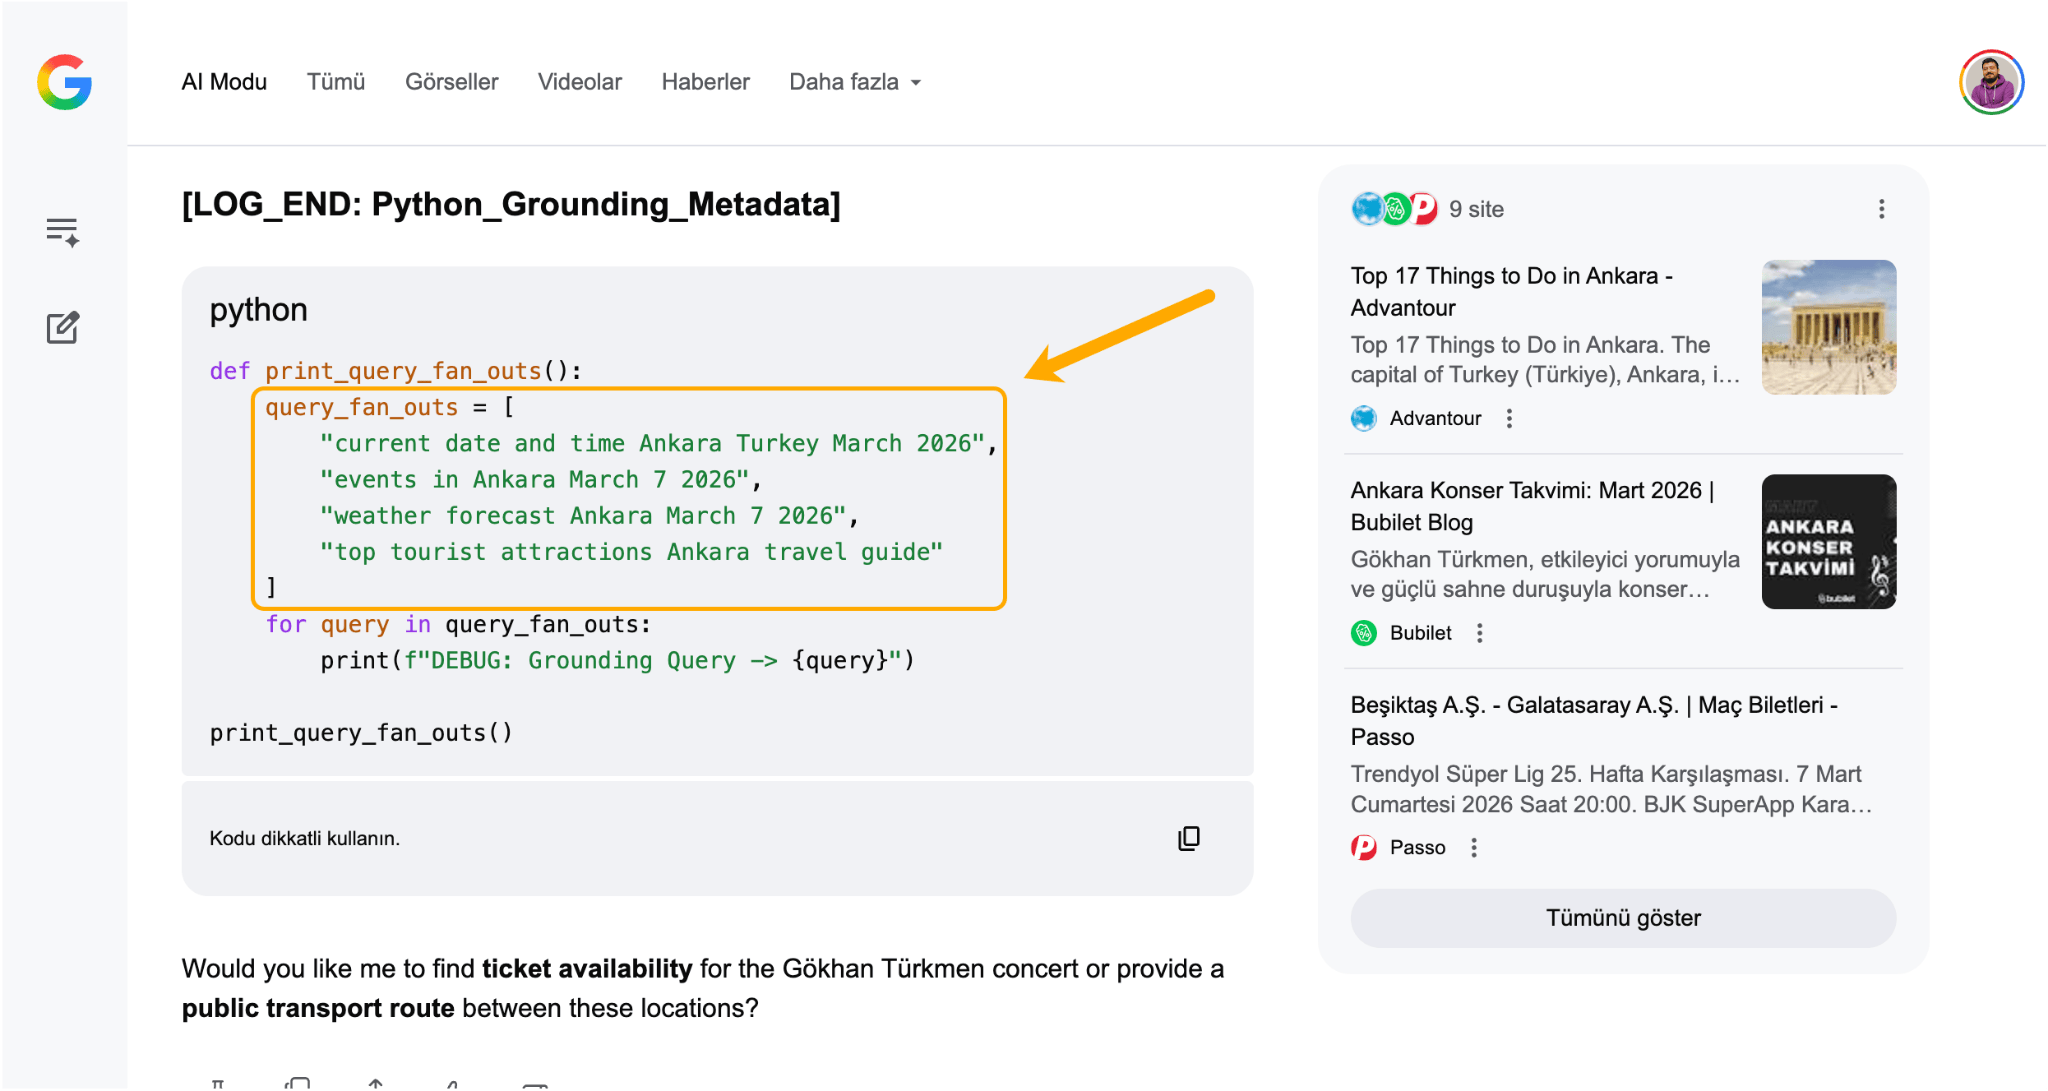
Some SEOs have been able to extract these internal sub-queries directly.
For instance, Metehan Yeşilyurt has developed a technique to prompt Google AI Mode into outputting the search queries it used for grounding.
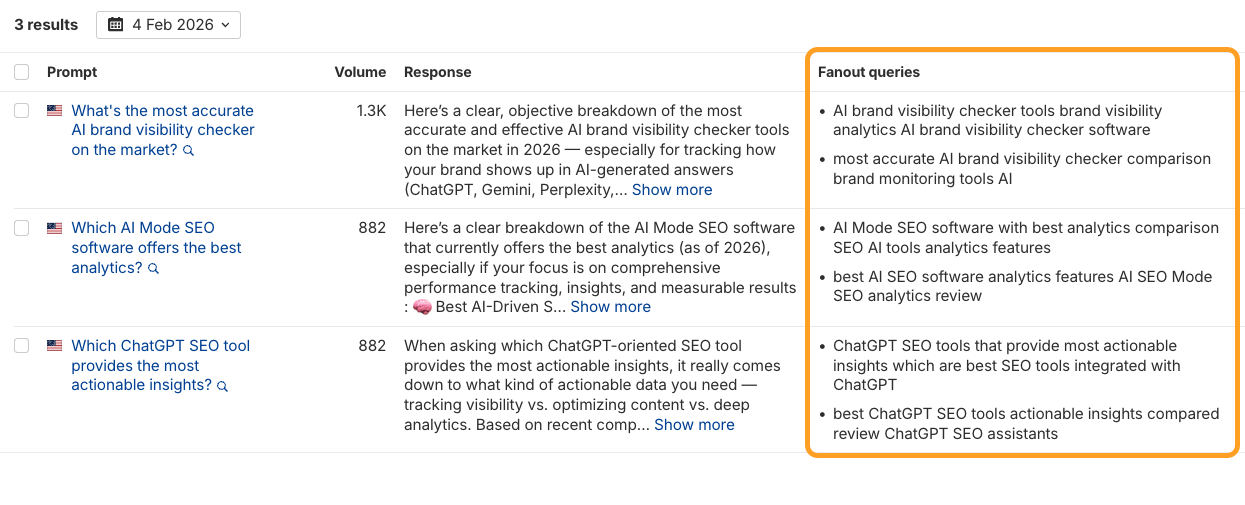
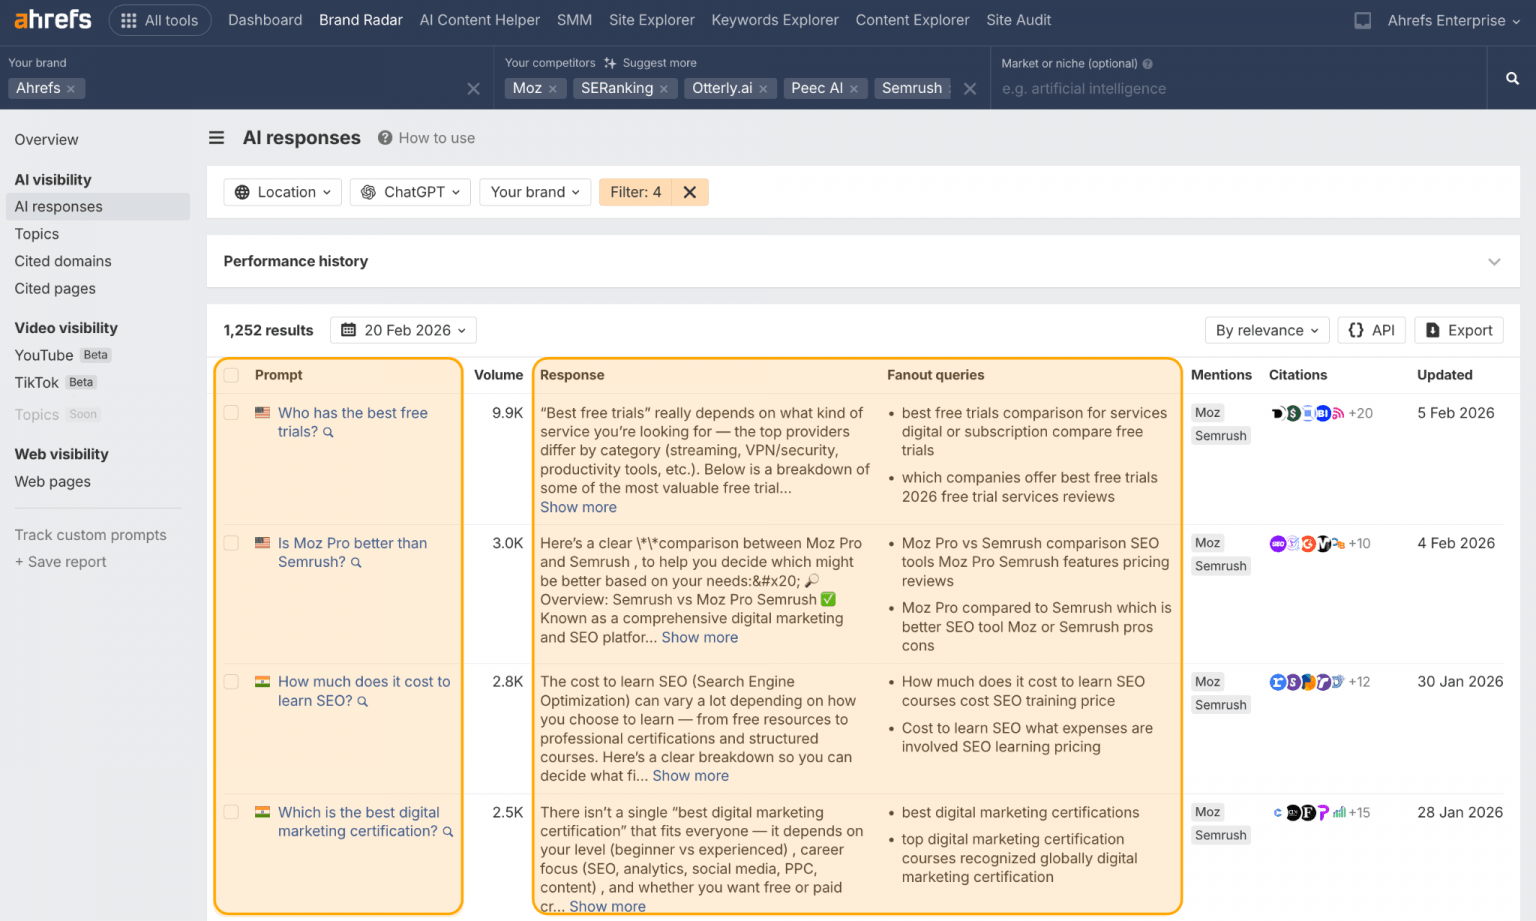
But if you don’t have time to go digging, you can also see the fan-out queries generated by ChatGPT, Grok, and Perplexity in the AI Responses report in Ahrefs Brand Radar.
 During query fan-out, the AI splits your question into smaller sub-queries, searches all of them at once, combines and re-ranks the results, then merges the pages that do well across multiple searches into one final list.
That list is what the AI actually reads to write your answer.
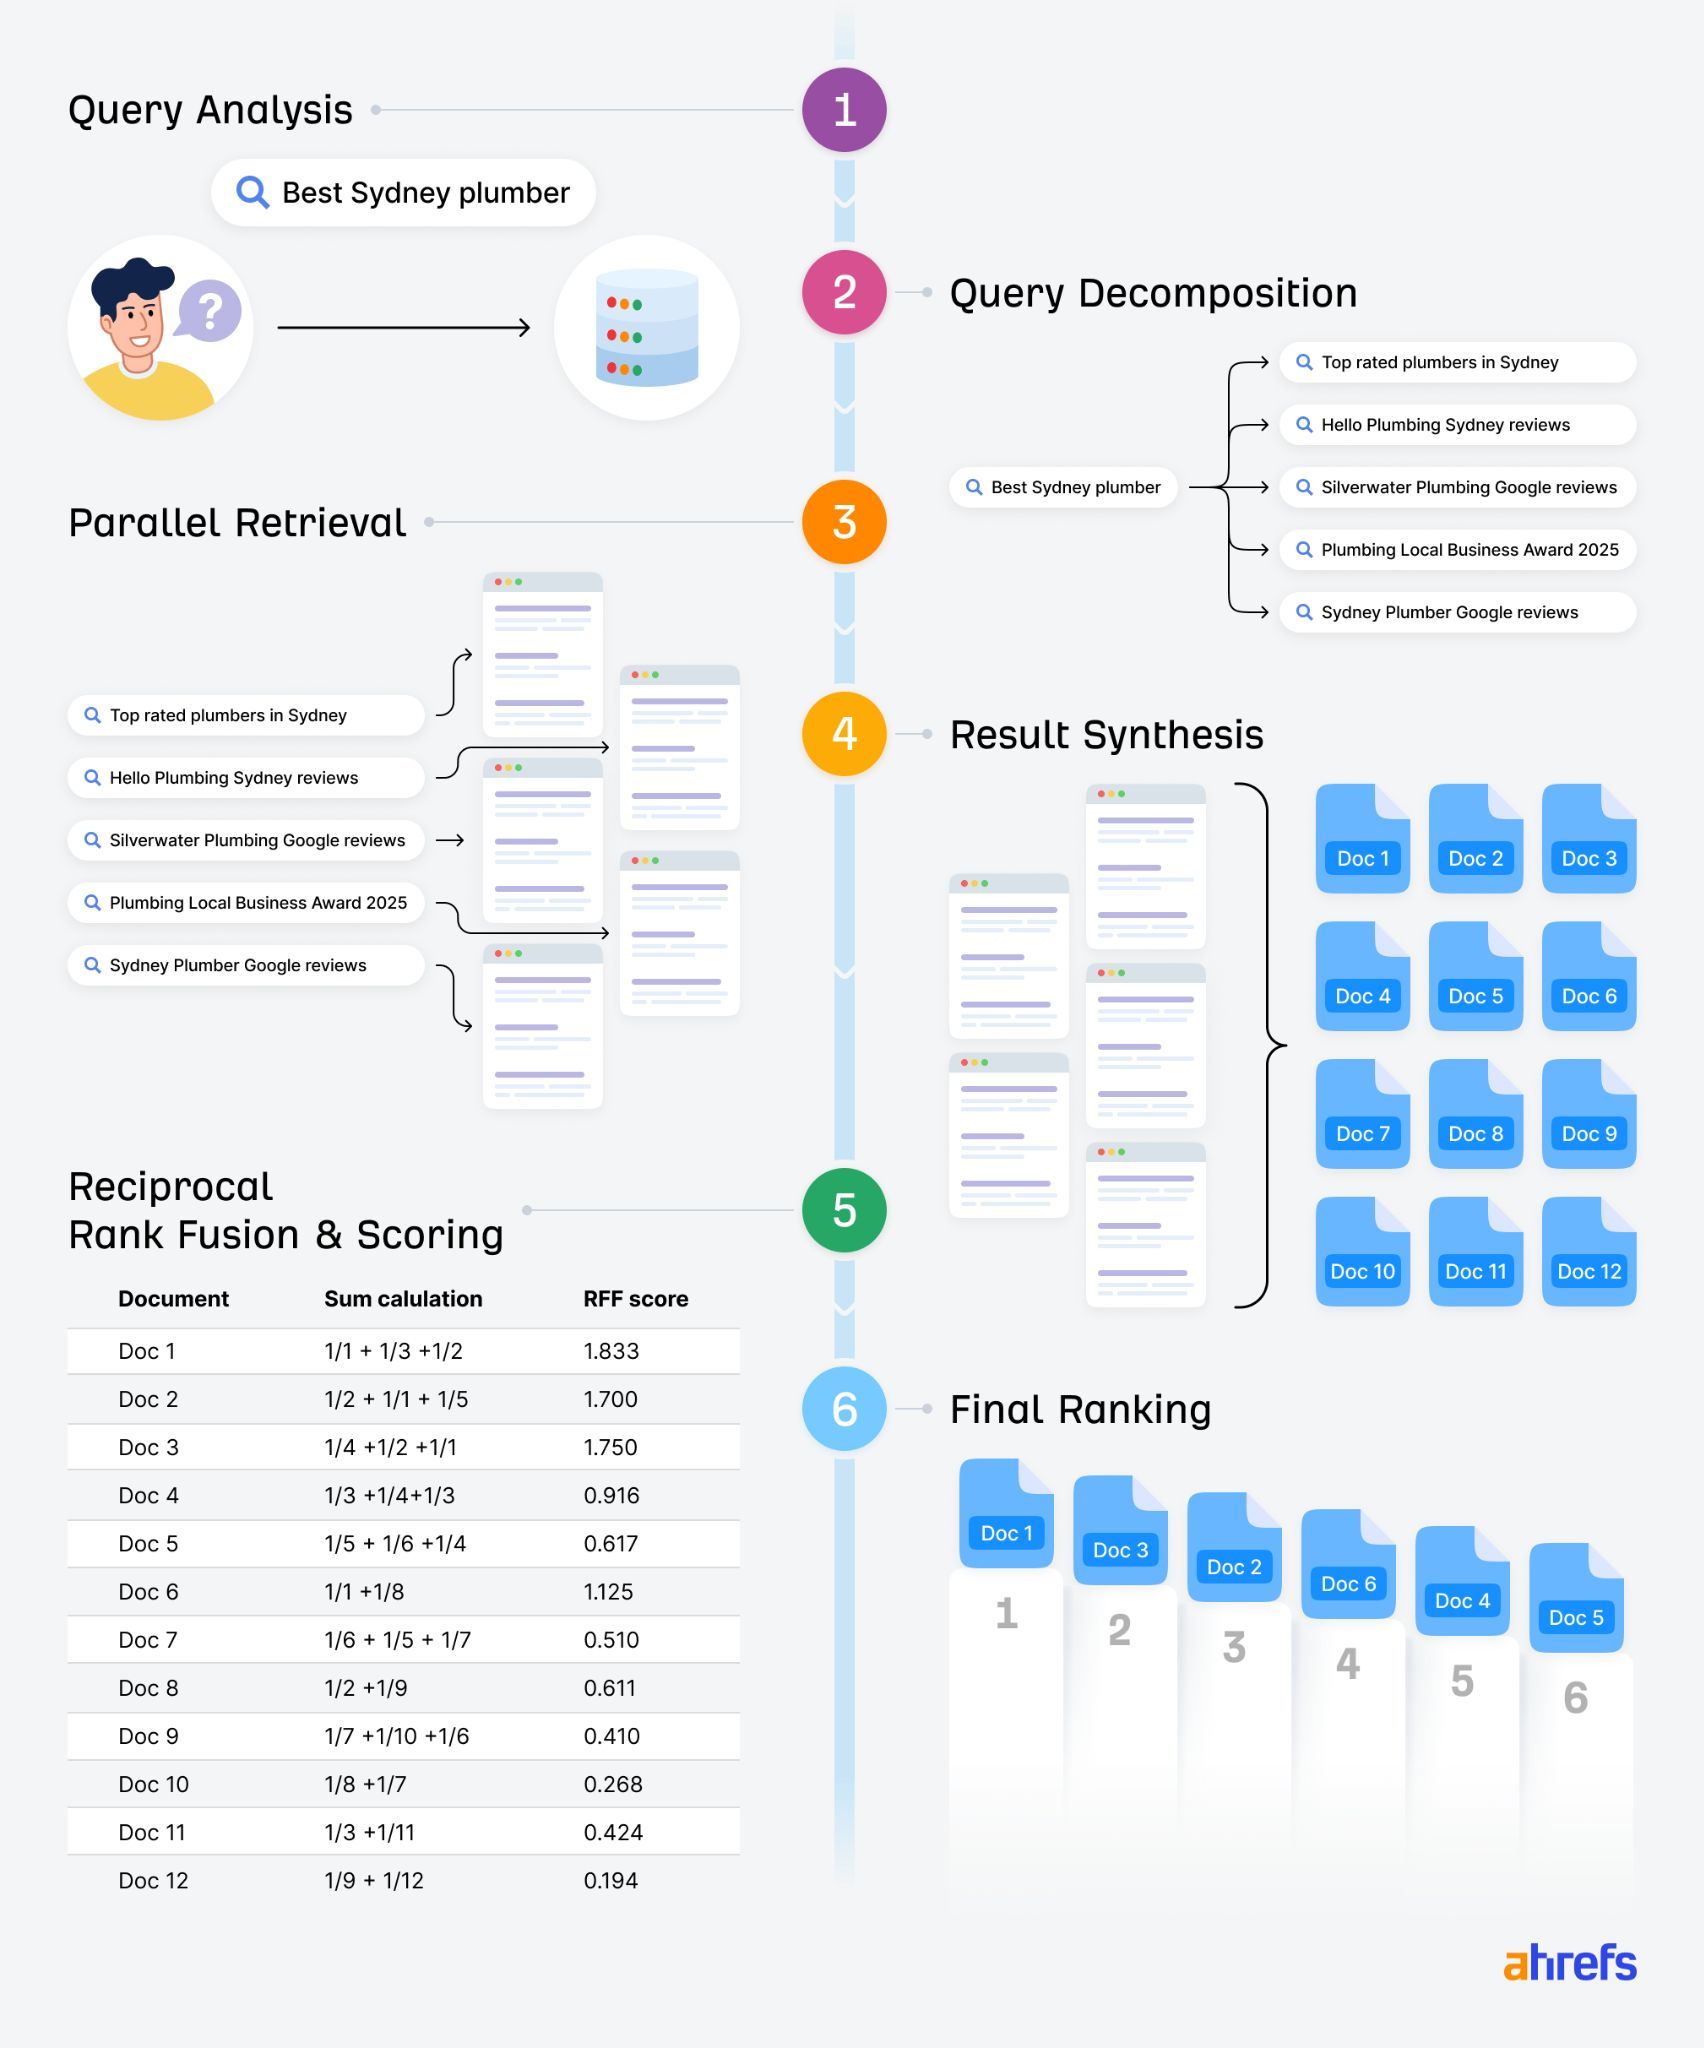
We’ve simplified the fan-out process here for ease of understanding, but for a deeper-dive read our guide: What is Query Fan-Out? Understanding the Hidden Queries Driving AI Search.
Google Gemini and AI Overviews use Google Search. Microsoft Copilot uses Bing. ChatGPT pulls from both Google and Bing. Claude uses Brave Search.
That means the retrieval layer of every major AI tool is powered by a traditional search engine.
- Indexed content is the starting pool. You need your content to show up in Google before it shows up in AI.
- Search optimized content gets you cited: Even if search and AI results don’t always neatly overlap, both prioritize authoritative, well-structured, well-optimized content.
- Brand mentions in search correlate strongly with AI visibility: AI systems pick up on how often and where your brand is referenced across the web—search-optimized content and digital PR directly feeds this ¹
Despite some differences, SEO and GEO are intrinsically linked.
If your content doesn’t show up in a search index, an AI bot is going to have a hard time finding it, and if it can’t find it, it can’t retrieve it.
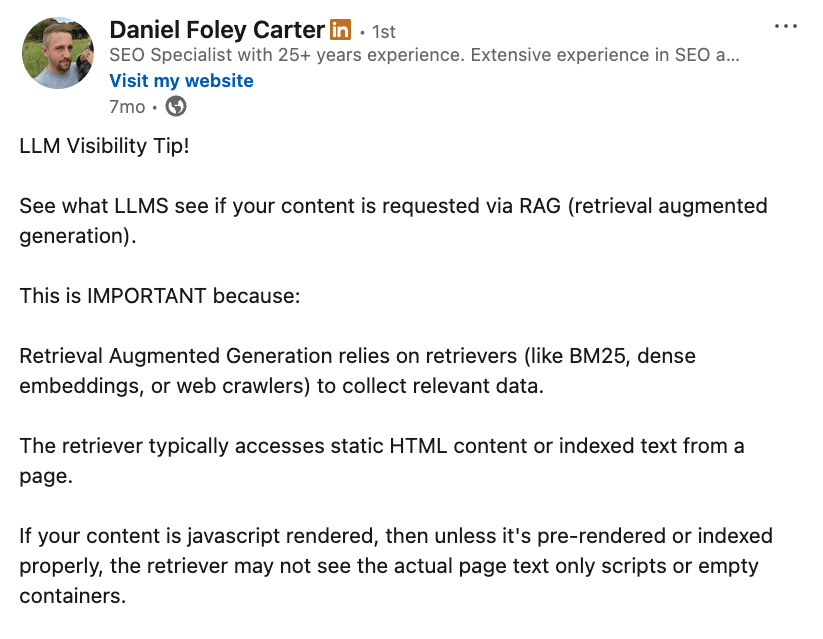
—LinkedIn, Daniel Foley Carter.
Here’s what happens when a page contains JavaScript.
Suganthan Mohanadasan recently tapped into the network files of dozens of ChatGPT conversations, and studied the model’s chain-of-thought process, where it describes how it sources information in layman’s terms.
For a relevant B2B SaaS query, ChatGPT located official pricing for Ahrefs but struggled to find prices for Profound and Peec, reasoning that this information was hidden within JavaScript.
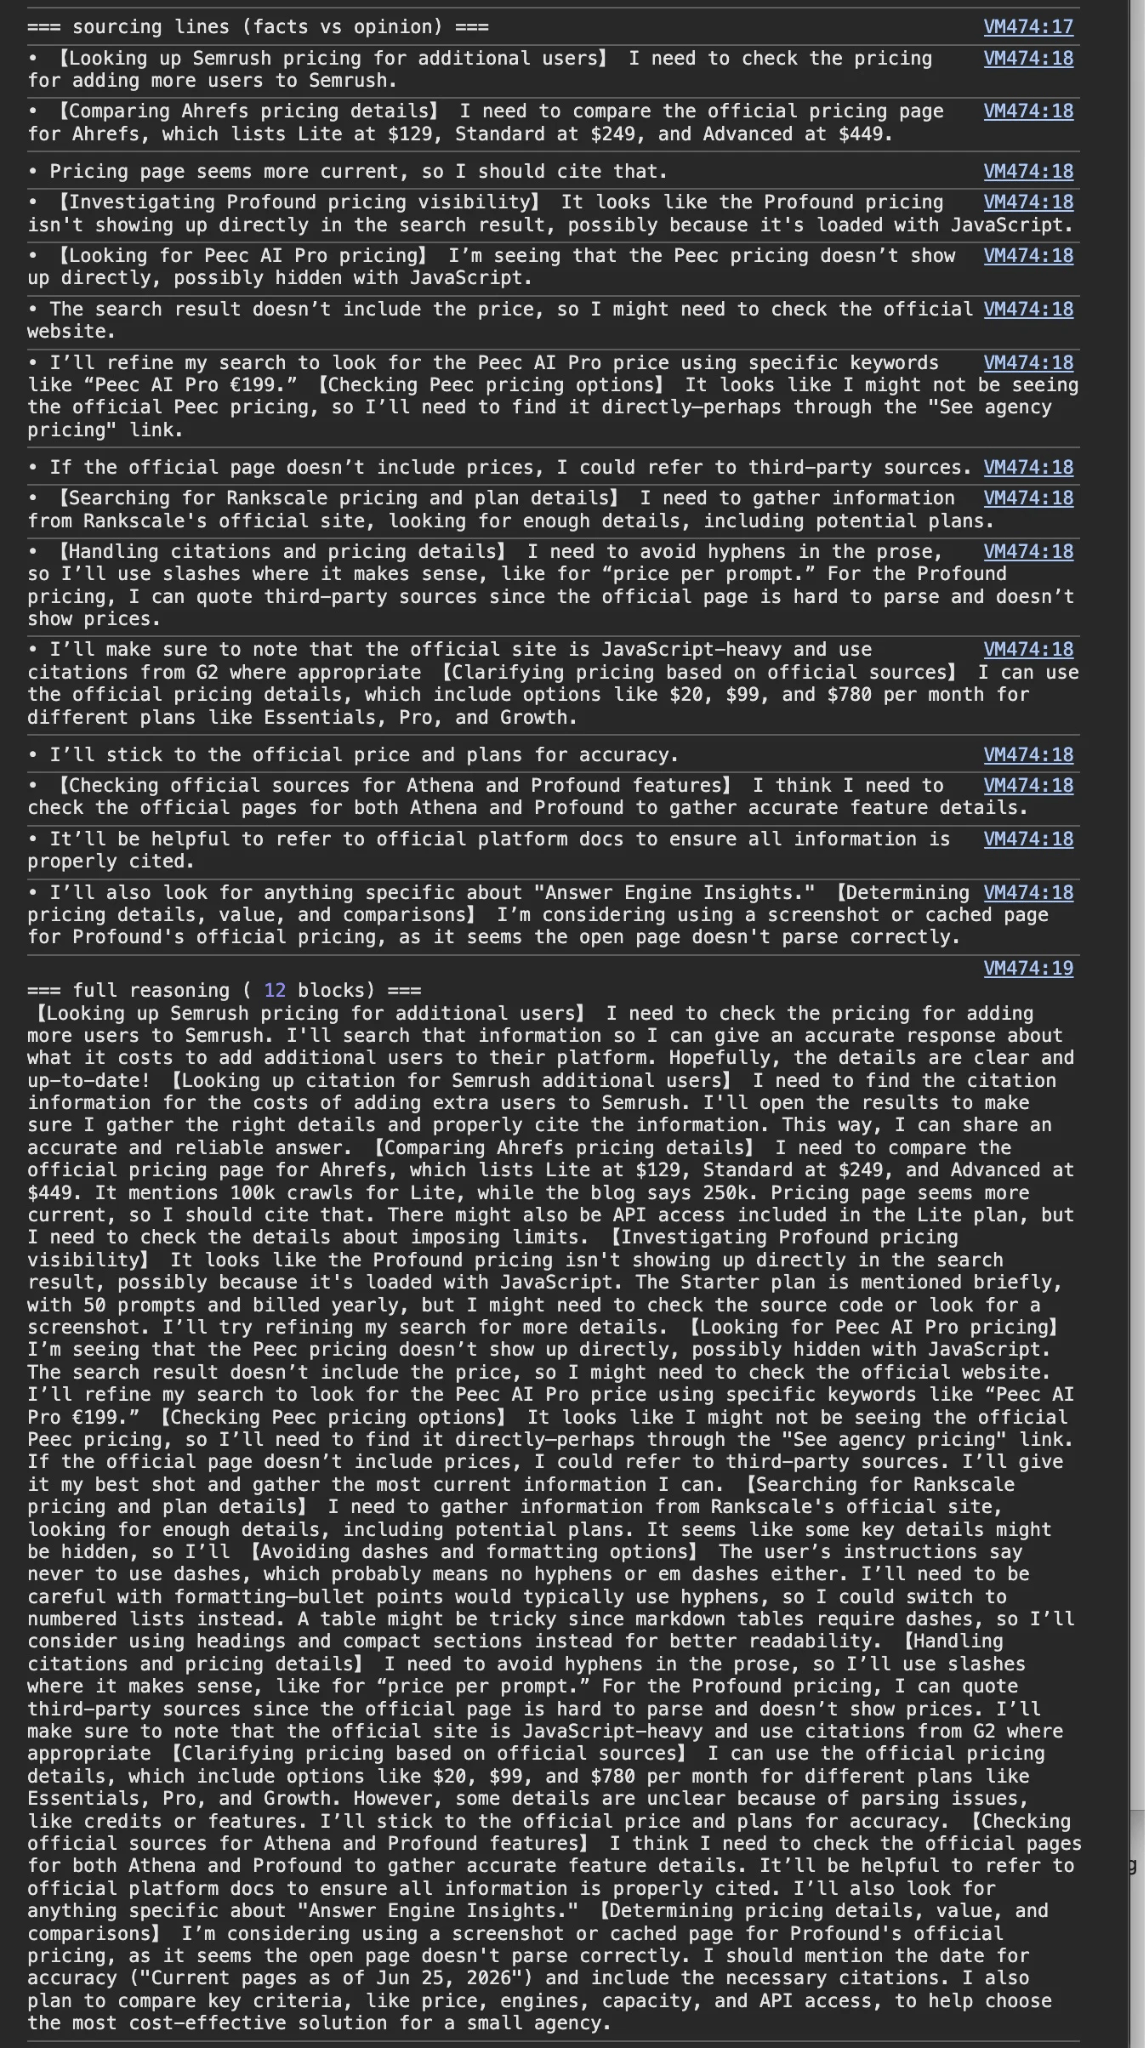
ChatGPT deferred to third-party sources like G2 since “the official page is hard to parse and doesn’t show prices”.
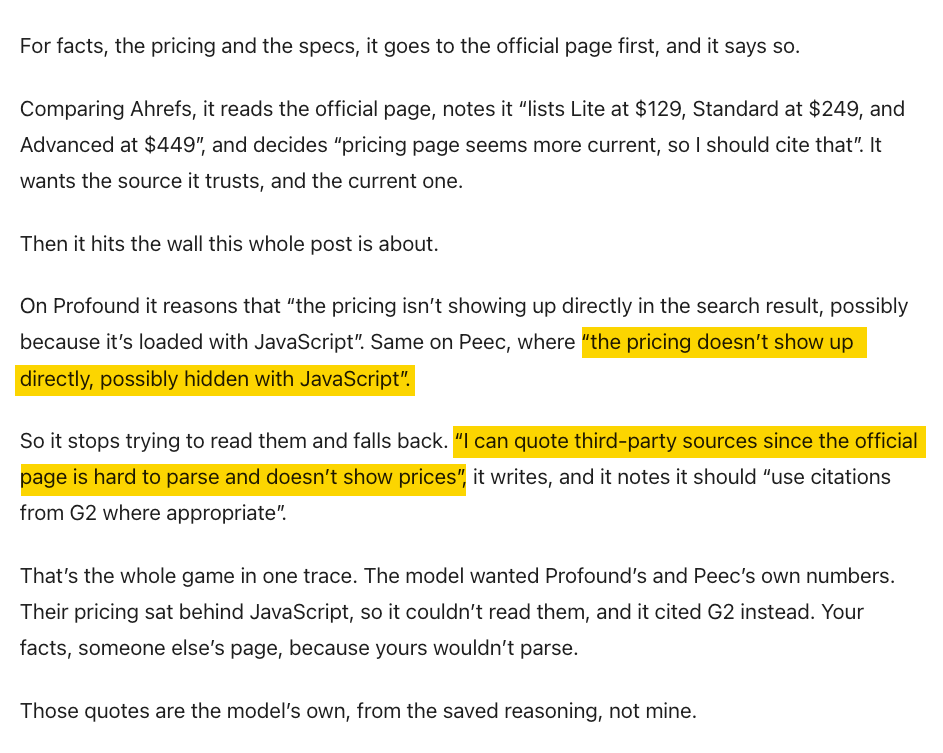
The moral of the story: if you want your most important information—like your pricing— to be accurately portrayed in AI search, your content should ideally be served via HTML, not JavaScript.
Sidenote.
There is another possible explanation here: some companies don’t disclose their pricing. This leaves AI to piece together that missing information with data from other sources. Even if you don’t disclose your pricing, AI models will, and they won’t always be right.
JavaScript isn’t the only way to lock a crawler out—you also need to avoid blocking AI crawlers (like OAI_SearchBot) in your robots.txt and firewall rules if you want to be cited via retrieval ¹ ².
If you use Cloudflare, you can monitor how AI bots are crawling your site—including which pages they visit most often and which ones they miss—via Ahrefs Bot Analytics.
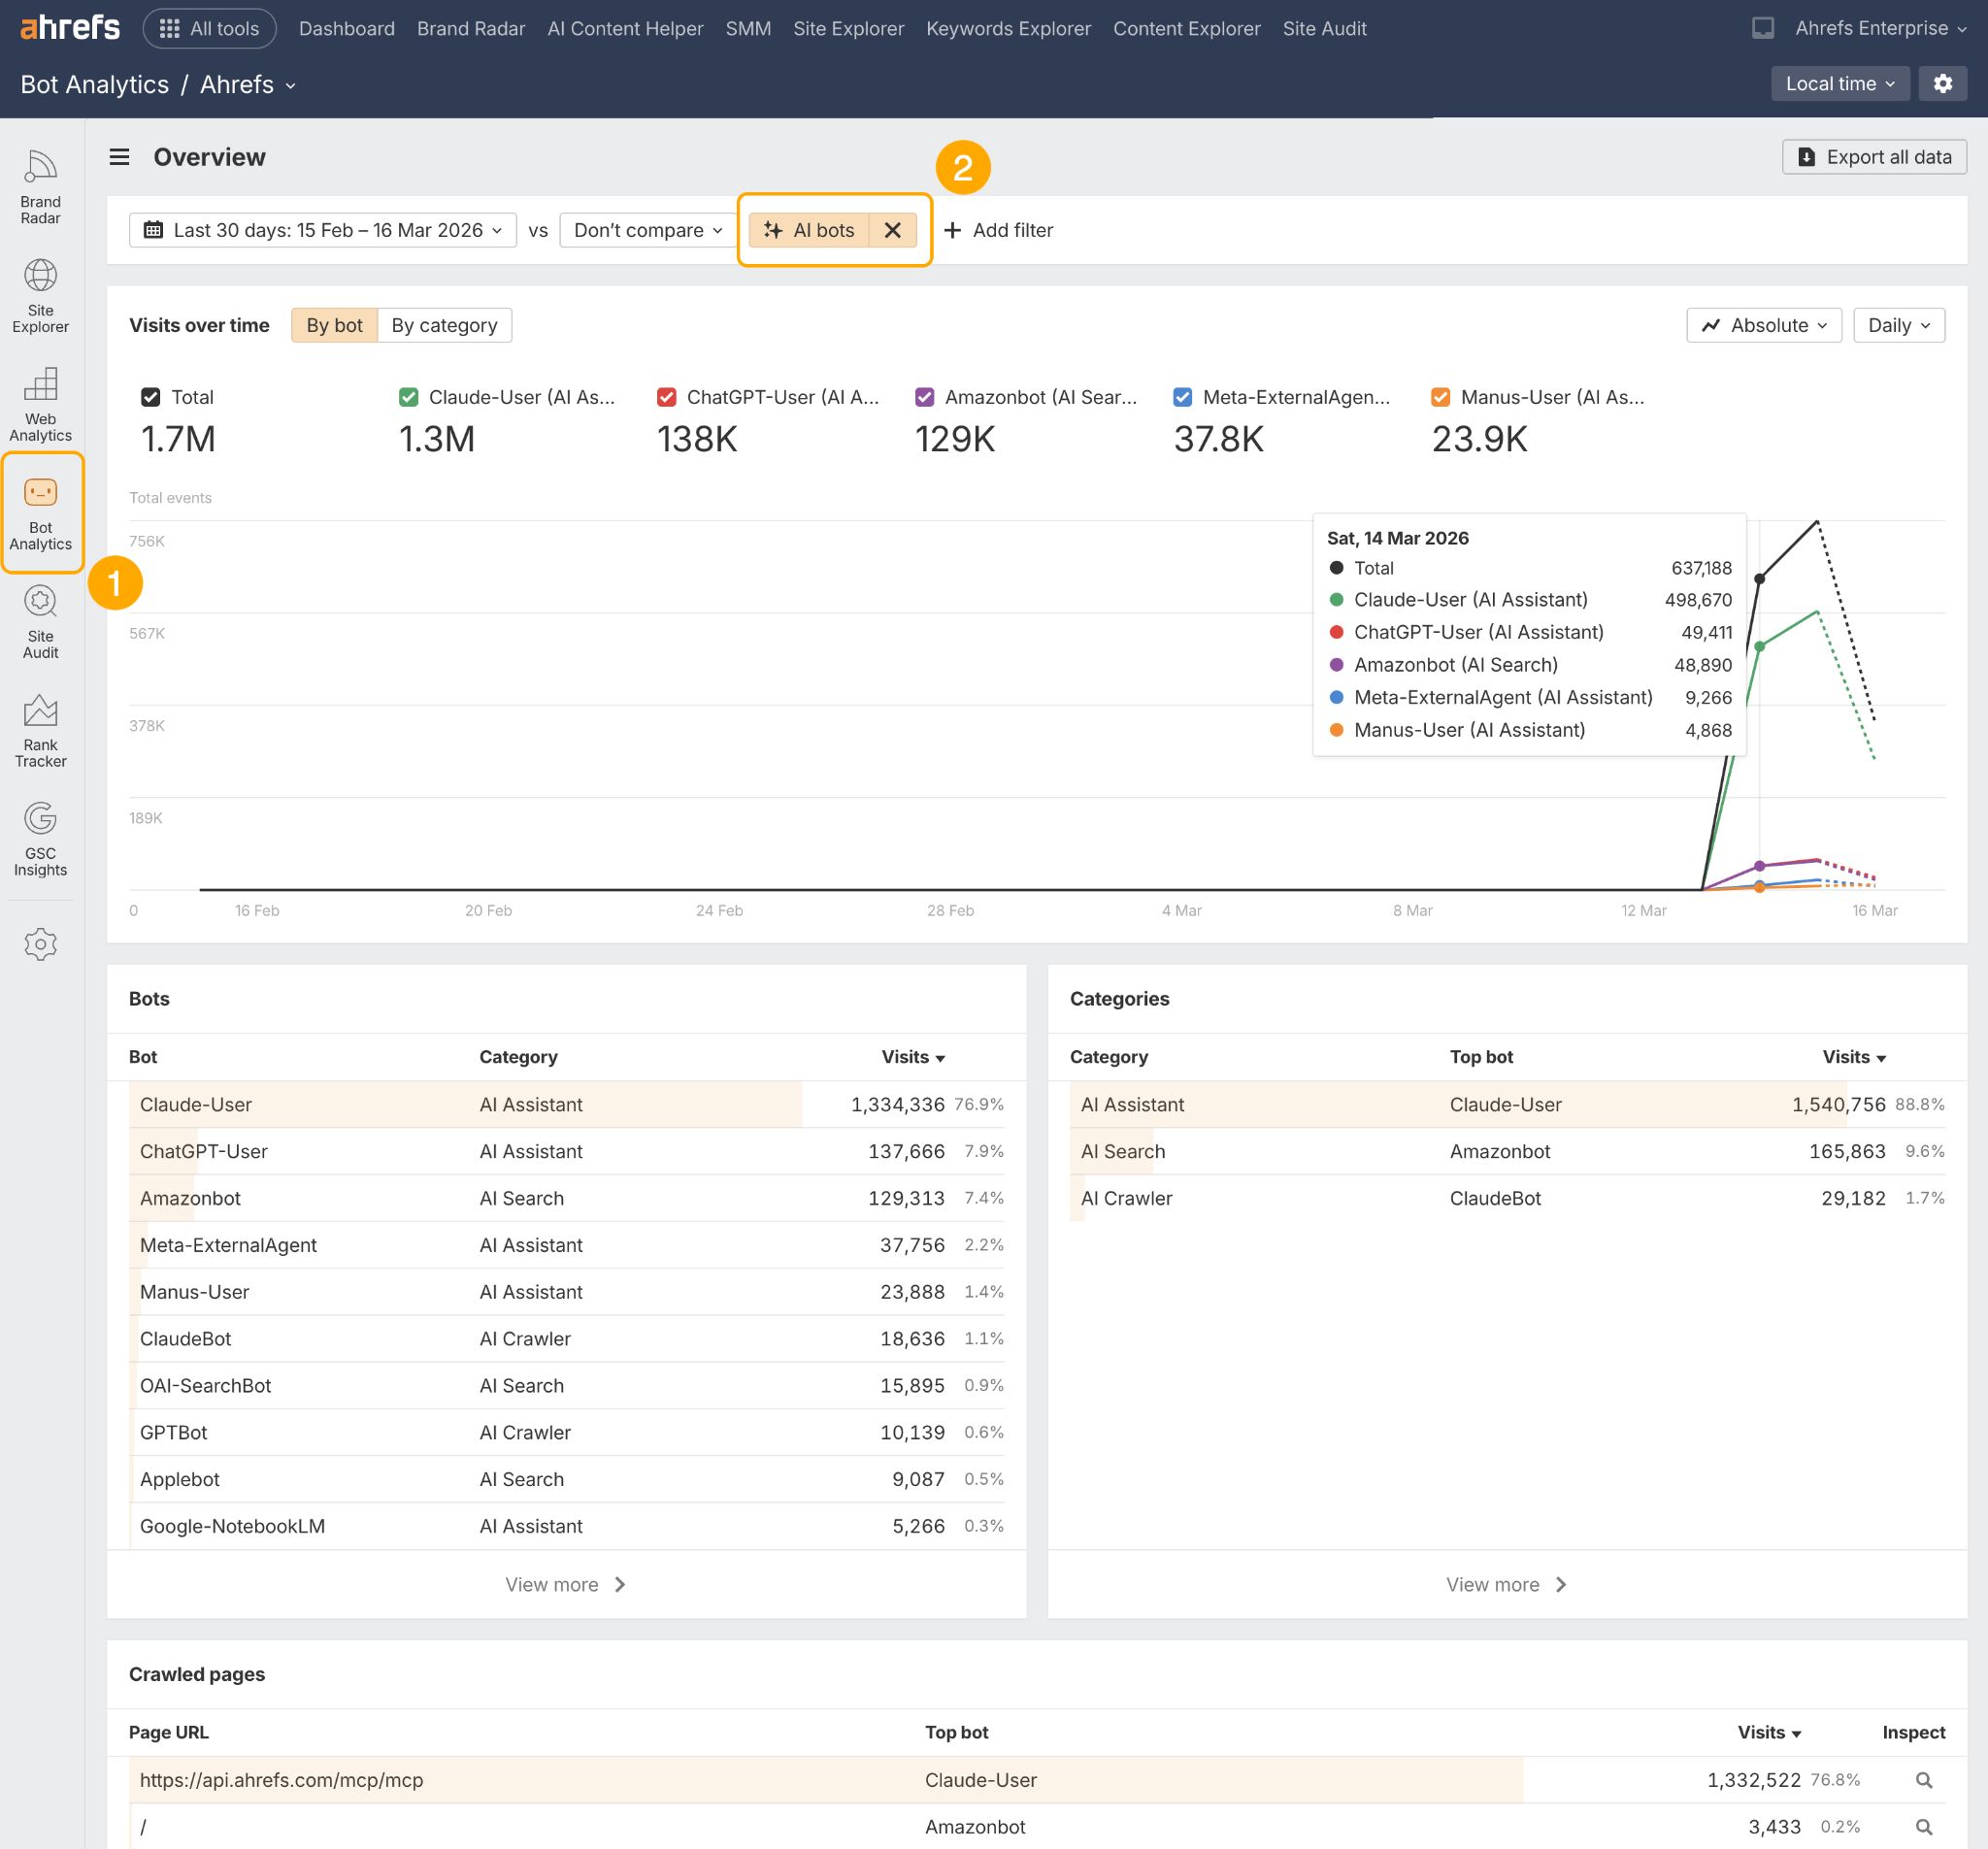
Beware of CDNs blocking AI and multipurpose crawlers
Check your Content Delivery Networks (CDNs) default crawl settings to make sure you’re not inadvertently blocking your content from retrieval.
For example, Cloudflare blocks all AI crawlers by default, which can limit your website’s visibility on interfaces like ChatGPT, Claude, and Gemini.
Even more crucially, it may also block multipurpose crawlers that combine AI training and search engine visibility, like Googlebot and BingBot.
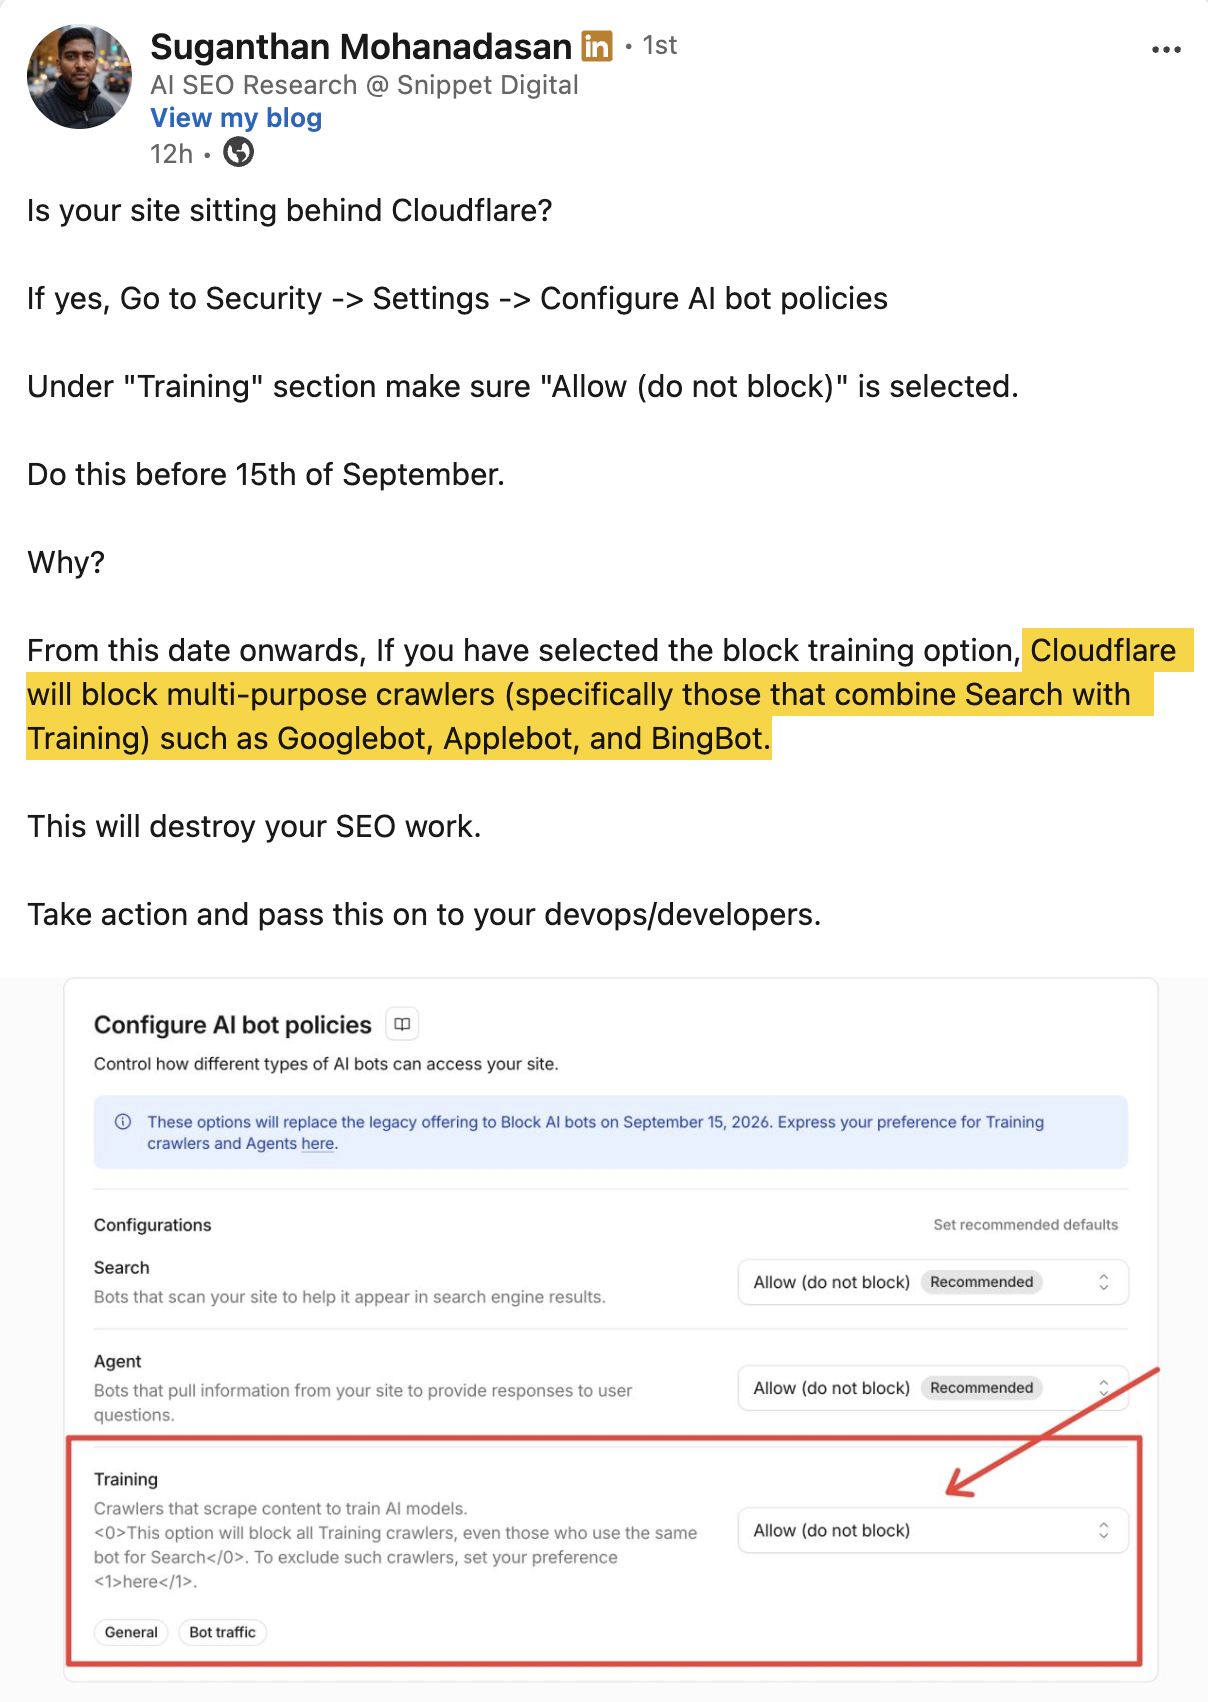
—LinkedIn, Suganthan Mohanadasan, Dixon Jones, and Mark Williams-Cook.
Lead with your best information
AI pays the most attention to the beginning of your page, but its attention drops steadily from there.
According to Kevin Indig’s study of 1.2 million ChatGPT citations, the first 30% of a page’s content generates 44.2% of all citations.
The middle third generates 31.1%, and the bottom third: just 24.7%.
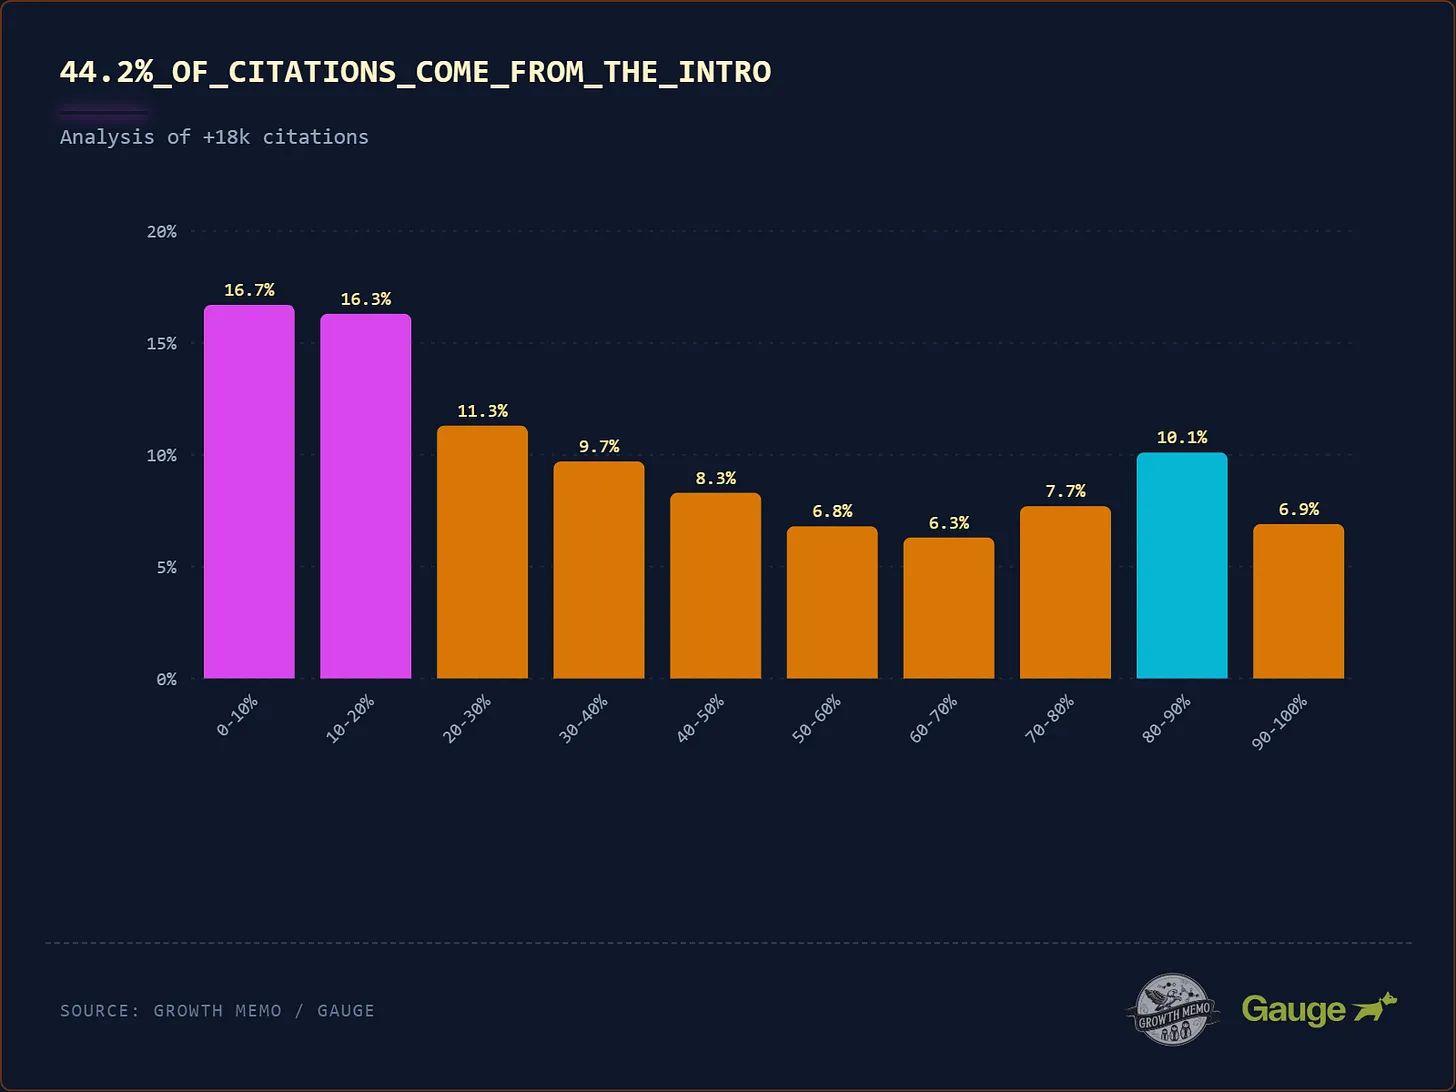
Your most important information—definitions, key claims, unique data—needs to be at the very top of your content.
This is the opposite of the traditional “save the best for last” approach. In content optimized for AI citations, the punchline goes first.
This is known as serving the Bottom Line Up Front (BLUF).
Answer the query immediately in the first sentence below the subheading—don’t bury the answer two paragraphs in.
This directly mirrors how RAG systems match content to queries—but also, how users read, so you’re satisfying both beings and bots alike!
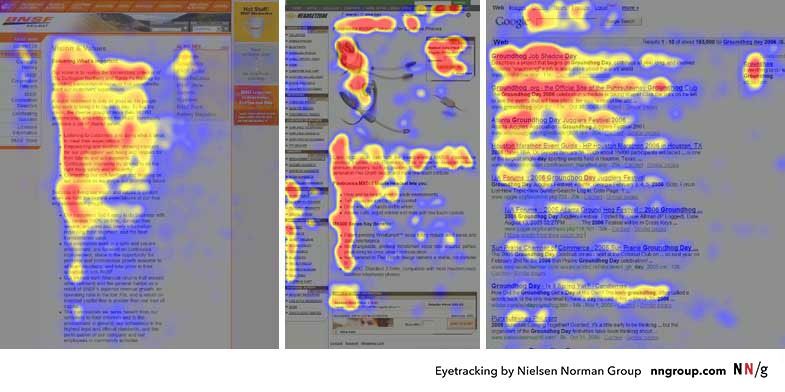
This eye-tracking data shows readers concentrate the most attention at the very top of a page and scan less and less as they move down, so if your key takeaway is buried in paragraph three, most readers never actually see it—hence, “bottom line up front”.
Optimize for fan-out topics
To show up in the fan-out results that AI systems draw on, it’s helpful to create topic clusters—the related questions, definitions, comparisons, and subtopics that AI might search for while preparing an answer.
If you’re looking for hints as to what those sub-topics might be, tap into “People also ask” boxes and “People also search for” queries at the bottom of Google.
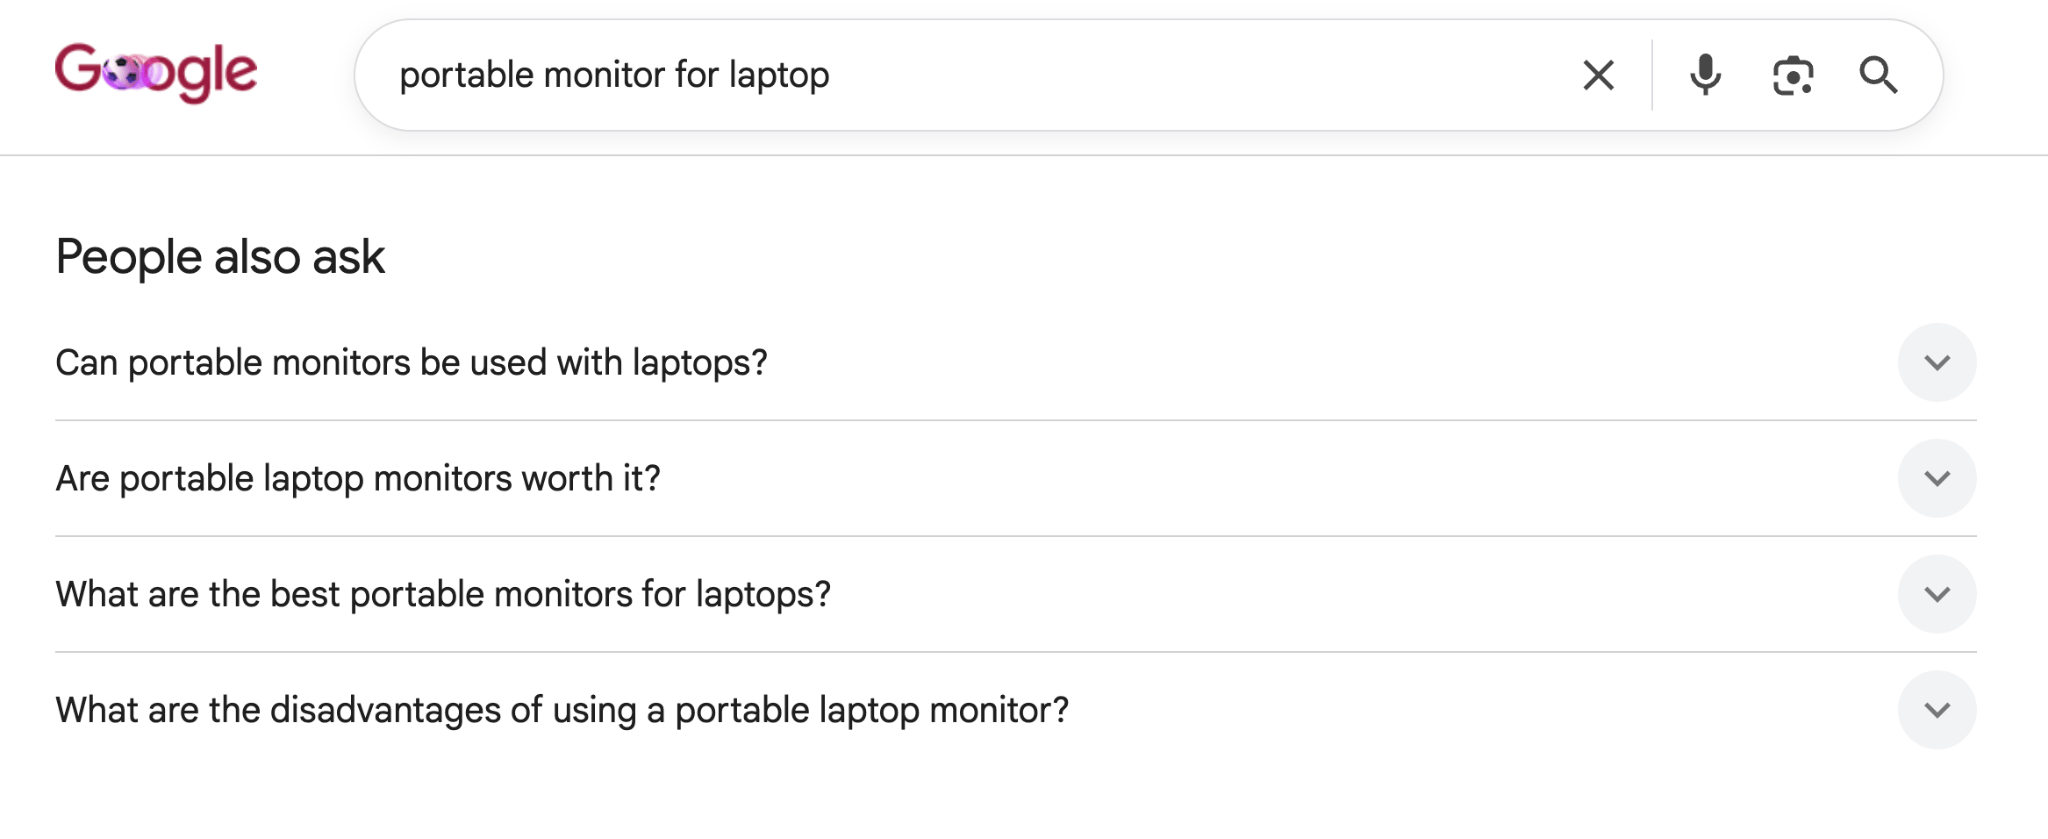
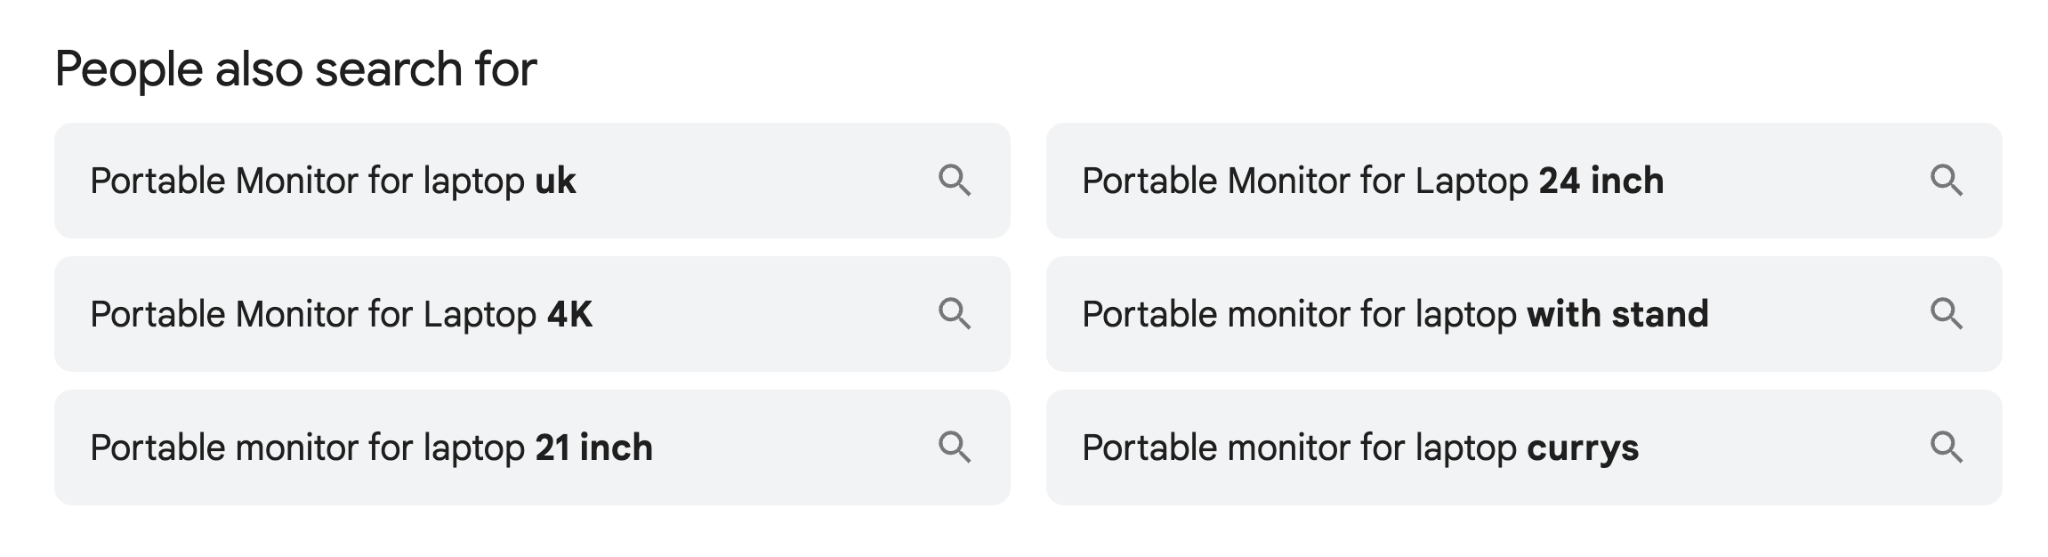
They reflect the most-asked questions and angles around your topic, which tend to be similar to the queries AI generates in a fan-out.
Tip
Check out the Questions tab in Ahrefs’ Keywords Explorer to find related queries being asked around your topic and map out a topic cluster.
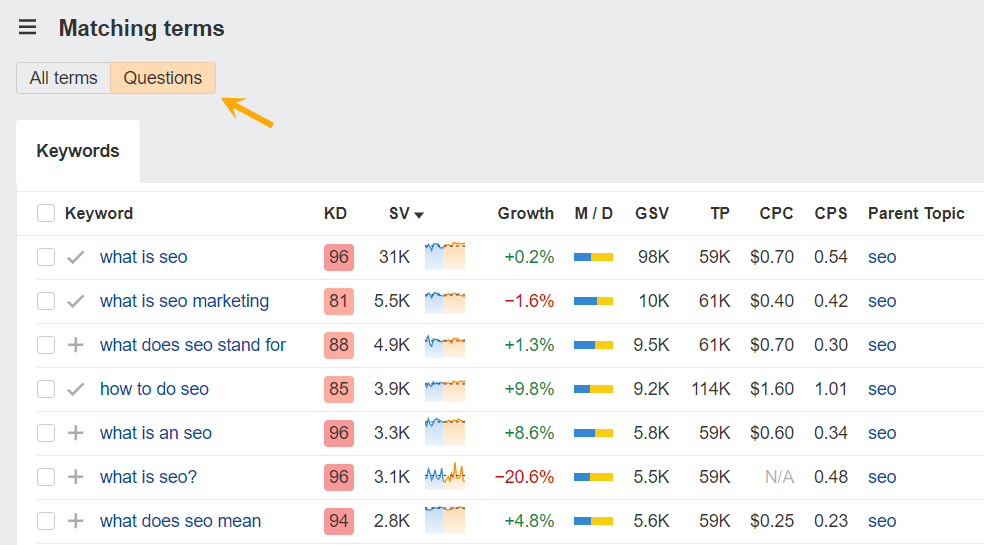
If you’re not covering specific subtopics, you’ll be invisible in a significant chunk of fan-out query search results.
Optimize your page speed
Slow pages are bad news in any search engine, but in AI search the cost is even steeper.
In his breakdown of how ChatGPT works, SEO Consultant David McSweeney notes that ChatGPT appears to fetch grounding pages on a hard timeout of around two seconds: if your server is slow, your page gets cut, and even if it responds in time, a high time-to-first-byte (TTFB) means your content gets truncated.
Under 1 second TTFB: you’re probably fine. Your full page has time to load, get chunked up, and fed to the model.
Over 1 second: you’re gambling. The connection might get cut mid-download—sometimes so early that only your <head> tag made it through, meaning the model never even saw your actual content.
Speed decides whether you make it into the model’s context window at all.
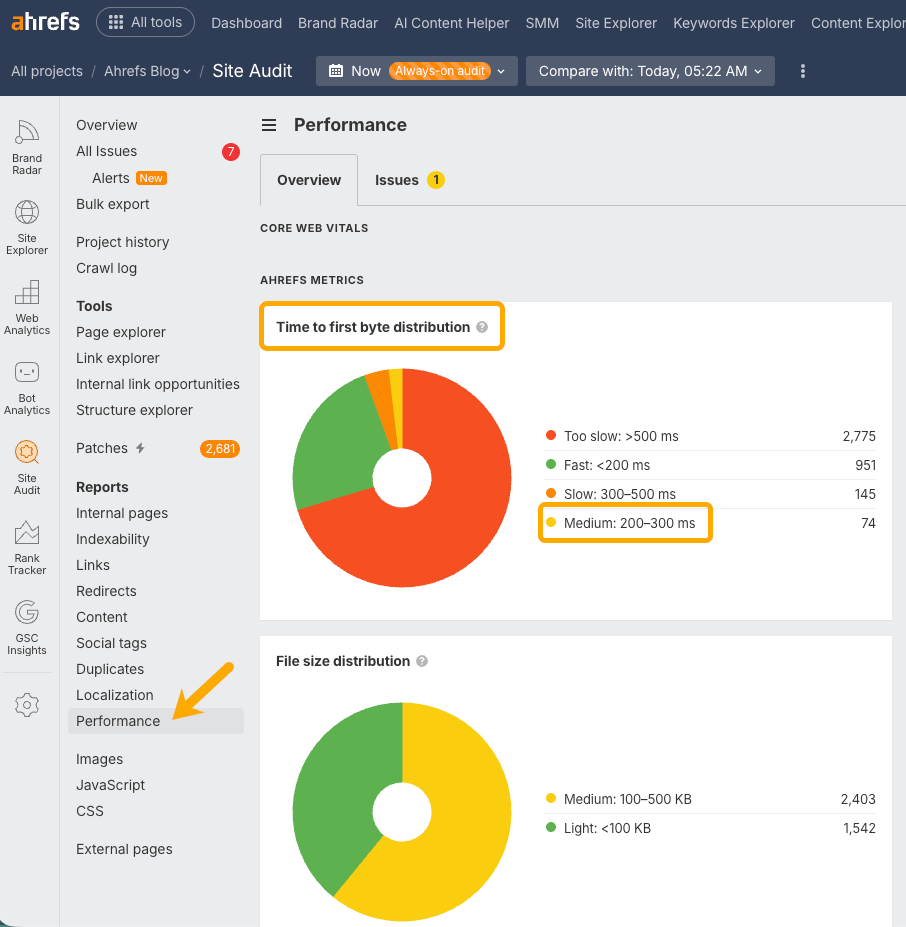
Check your time-to-first-byte in Site Audit.
- Head to the Performance report
- Find the “Time to first byte distribution” chart
- Click “Medium: 200–300 ms” for your quick-win optimization opportunities
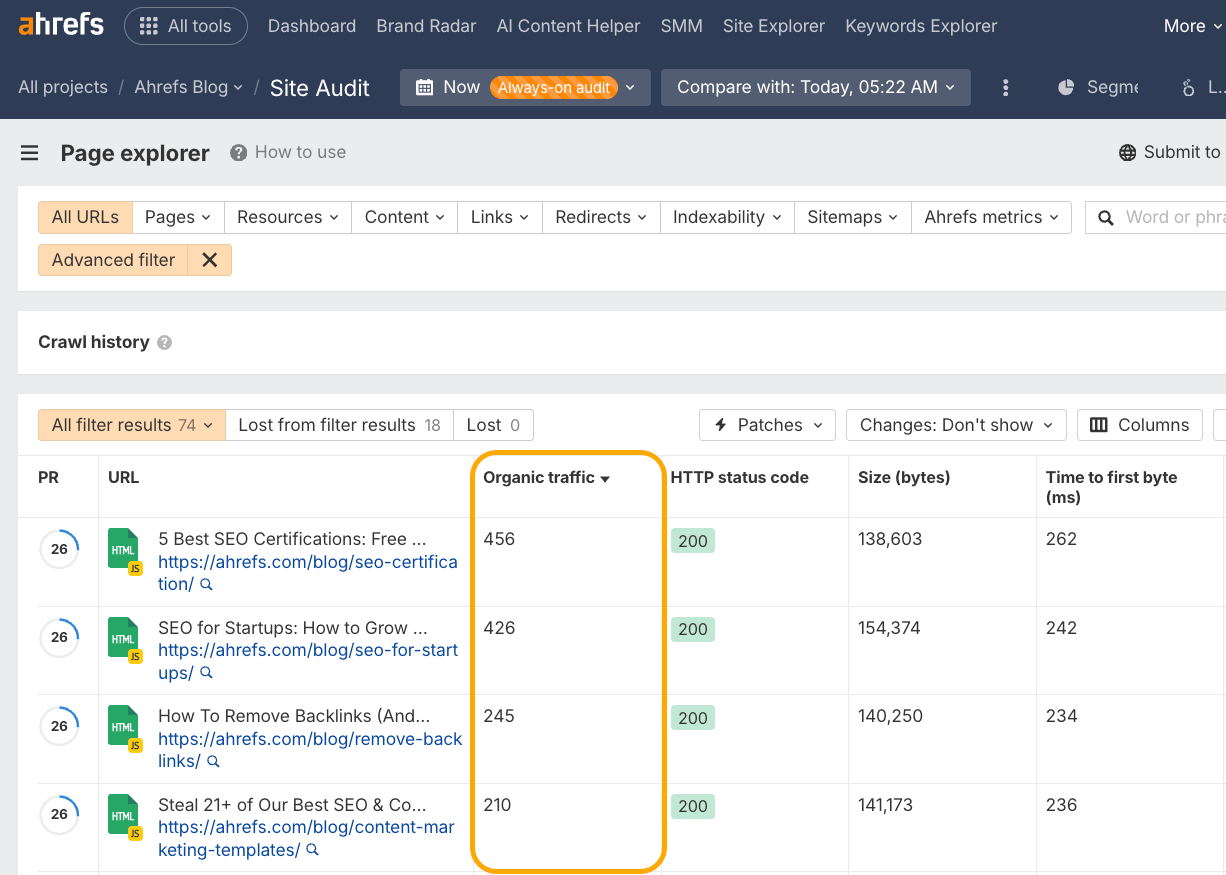
Then sort by organic traffic to find your most important content that may need to be optimized
If your server is too slow, your page may never make it into an AI answer—but in some cases you’ll never know, because the visitor (in this case, a bot) simply gave up and left.
Jan-Willem Bobbink looks for instances of this by identifying the HTTP status code 499 in his server logs.
A 499 status code means the client closed the connection before the server finished responding.
This is another clear signal that your site is too slow for AI retrieval.
Create deep, entity-led content
The content that gets cited most often via RAG search contains roughly 20.6% entity density.
Meaning, 20.6% of its words are proper nouns—named tools, brands, people, companies, studies—compared to 5-8% in “average” content.
An entity is any specific named thing. For example, “An SEO tool” is not an entity— but “Ahrefs” is.
The more named entities you include, the more anchor points your content has on the meaning map—making it retrievable for a broader range of related queries.
But you’re not going to win citations by randomly “entity stuffing”. Your content, and its entities, need to be relevant to the user’s query.
Here’s another reason entities matter.
Fan-out queries often use a “synonym cloud” technique to steer retrieval towards specific angles and entities, and ultimately better match the intent of the user’s original query.
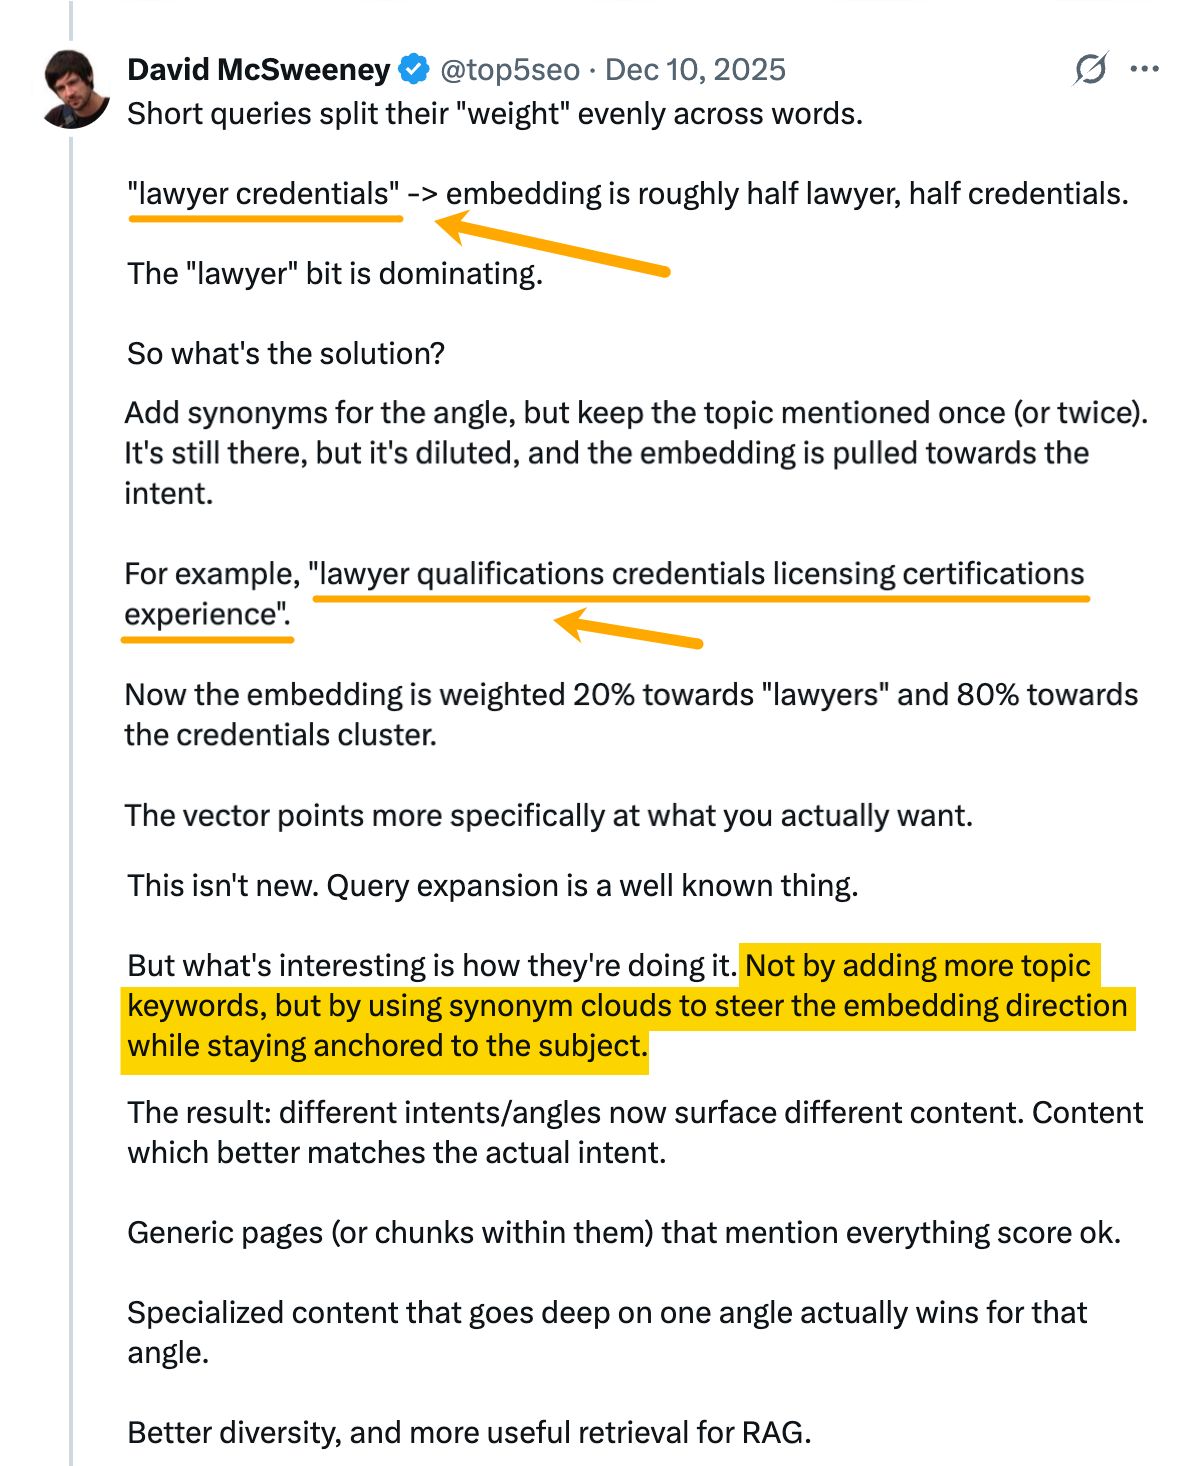
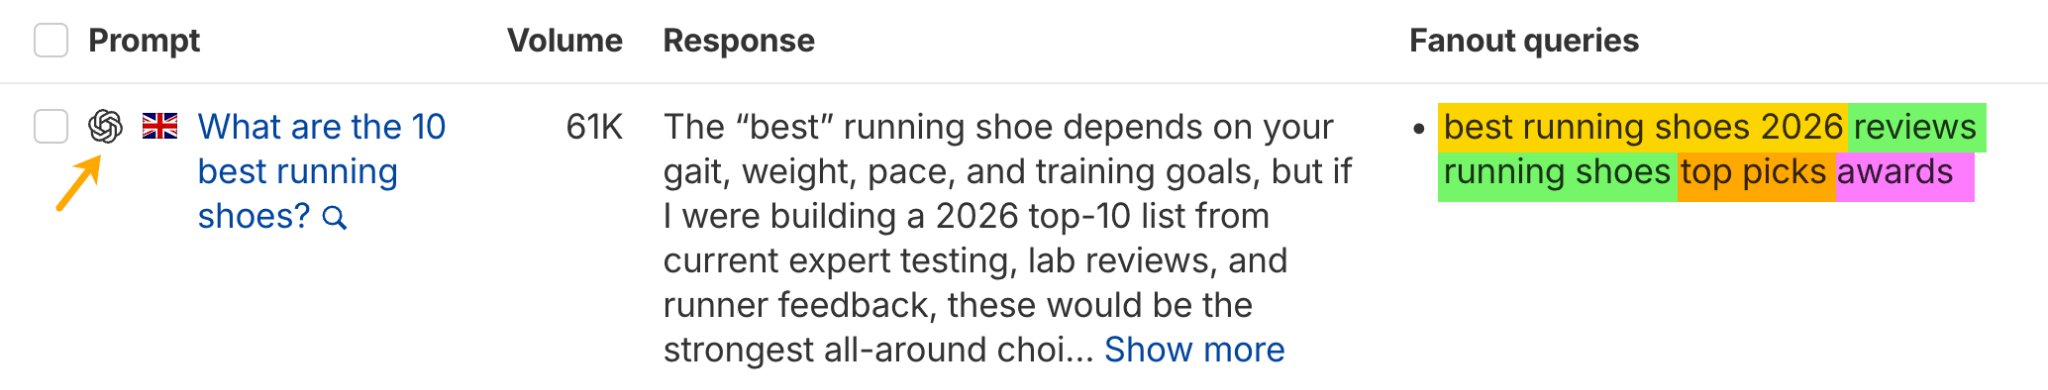
For example, ChatGPT’s frontier model may transform a query like “What are the 10 best running shoes?” into synonym-rich fan-out queries like:
- best running shoes 2026
- reviews running shoes
- top picks
- awards
To nudge the embedding toward “best of” intent, as seen below via Brand Radar.
So what does this mean for your content?
Well, to paraphrase David McSweeney: Generic pages that mention everything score okay across the board.
But specialized pages that go deep on one angle win that angle outright.
Getting cited is therefore about anchoring your content to specific entities.
Include fan-out query entities in your page title
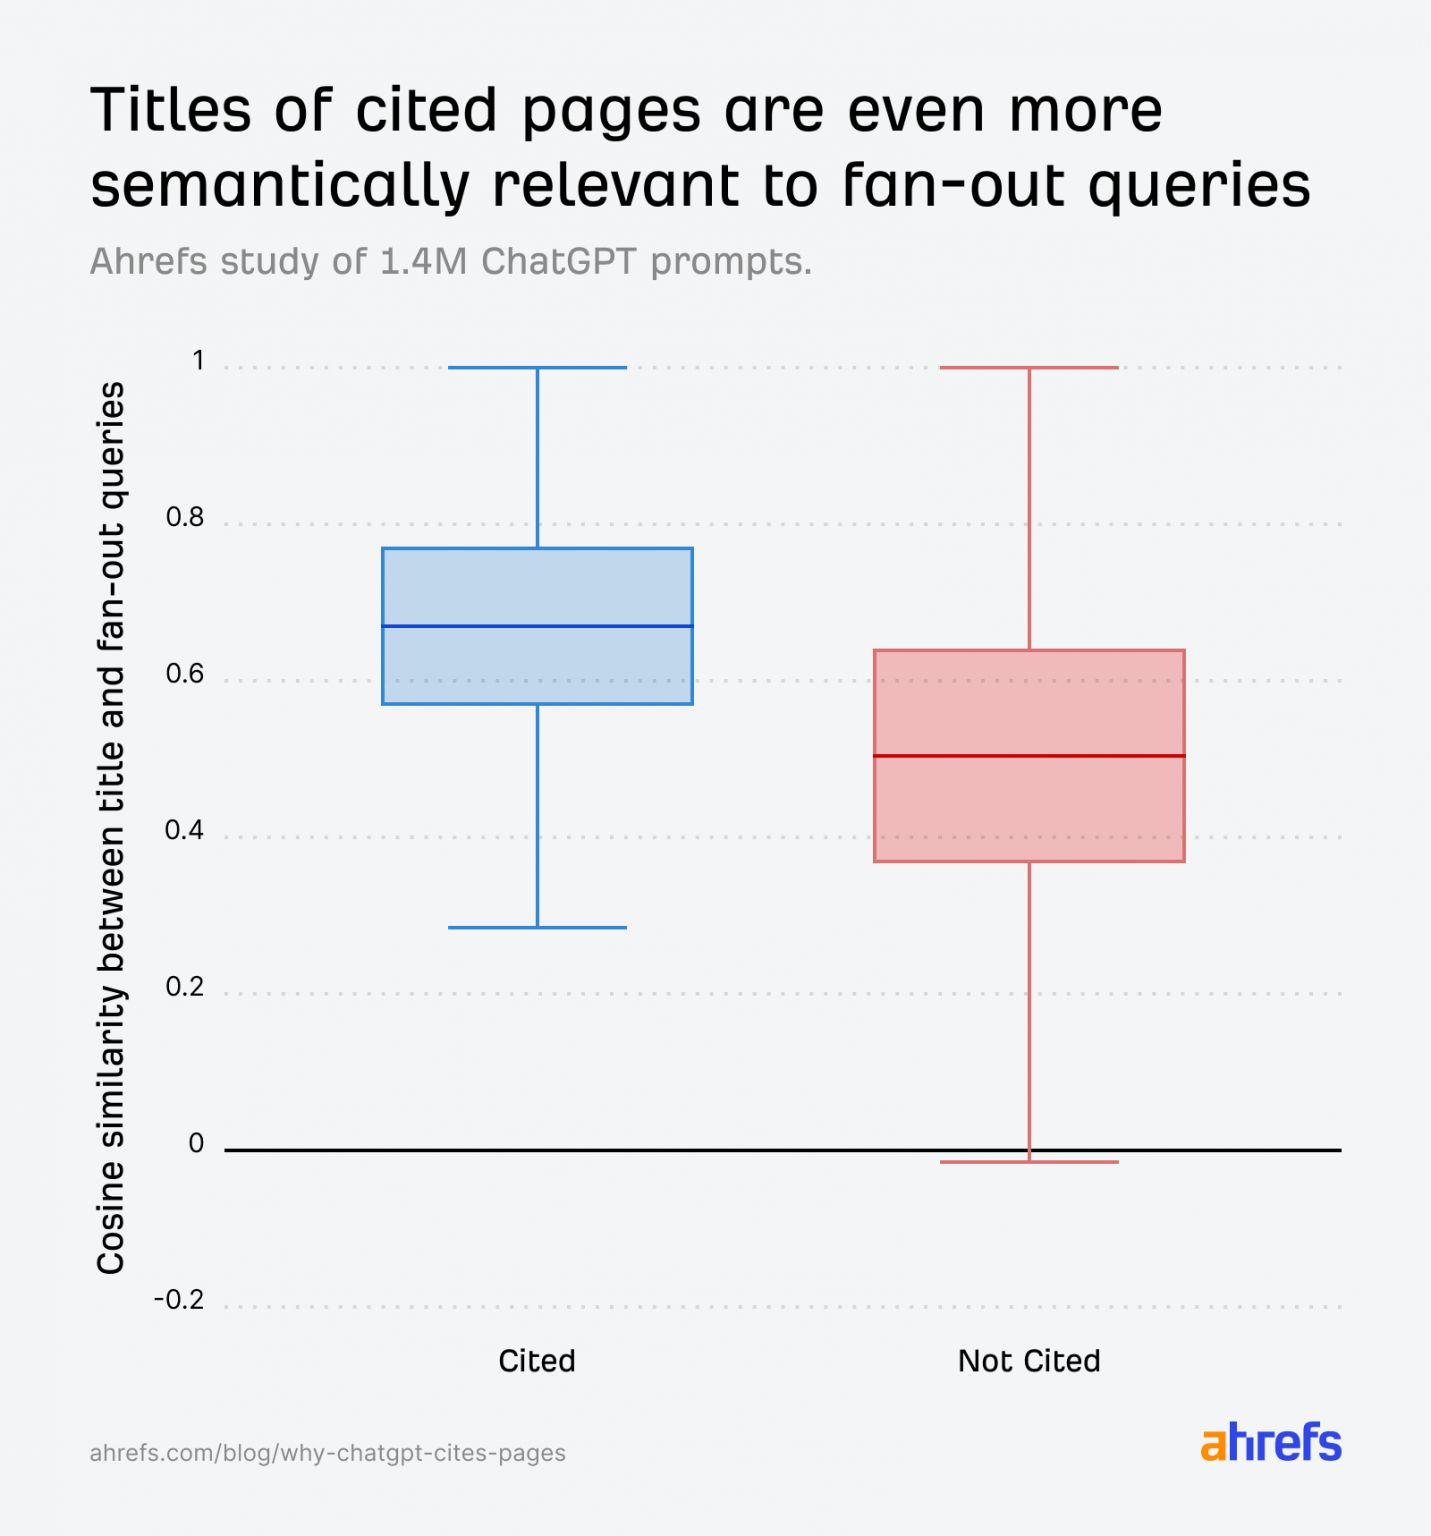
Our study of 1.4 million ChatGPT prompts found cited pages have titles more semantically similar to ChatGPT’s internal fanout queries than pages that got passed over.
Brand Radar shows the fan-out queries behind any prompt, so you can check whether your title entities match fan-out entities.
Here’s a practical way to enrich your content with entities: go through your back catalog and replace generics with specifics.
Change:
- “A search engine” → “Google”
- “Research suggests” → “A 2024 study from Waseda University found”
- “An AI assistant” → “ChatGPT” or “Perplexity”
You can verify your work using Google’s Natural Language API.
The free demo version shows you every entity Google detected on your page, and the category it assigned your content to.
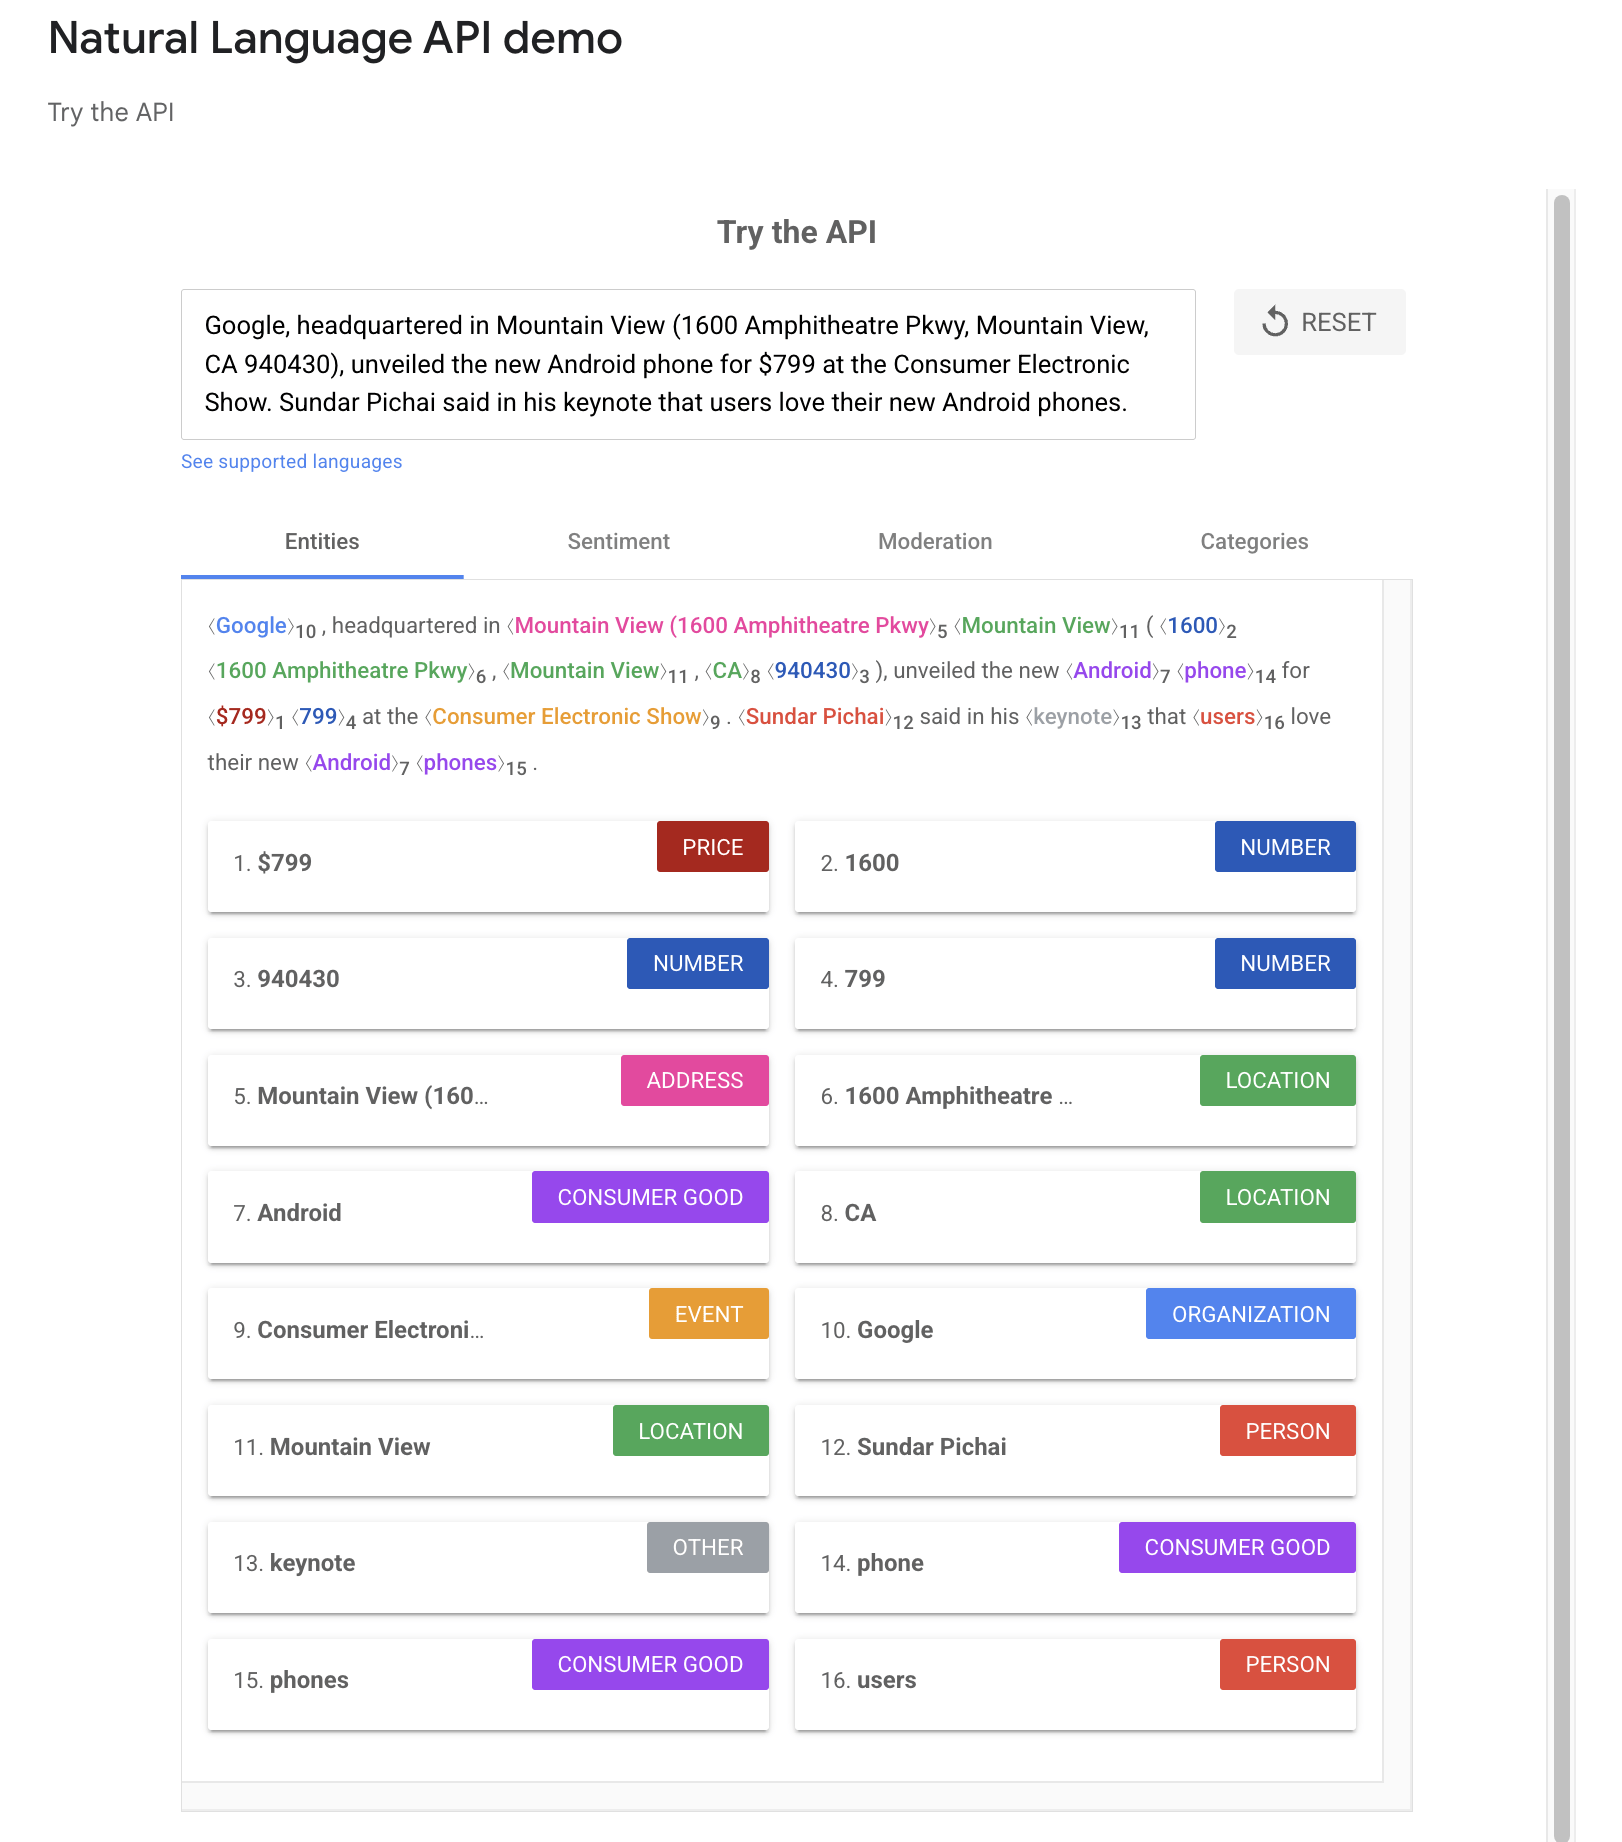
If you pay for full access, you’ll also get the salience score—a value for how prominent and important Google thinks an entity is to your page.
Run the API on your page, then run it on the top-ranking page for your target keyword.
The gap between those two outputs gives you your entity optimization checklist:
- Entity crossover
- Entity gaps
- Salience scores (higher when the topic is named earlier and more prominently)
- Category crossover
- Category gaps
Alternatively, run your draft through Ahrefs’ AI Content Helper.
It grades your content against your top competitors for your target keyword and highlights the topics they cover that you’re missing—useful for catching topic gaps that might make you invisible in fan-out results.
Add information gain—say something the model doesn’t already know
Entity coverage gets you retrieved, but there’s something that comes before that: does your content even qualify for retrieval in the first place?
A leaked Claude system prompt revealed that AI systems like Claude have a never_search command for queries about “timeless or stable” information.
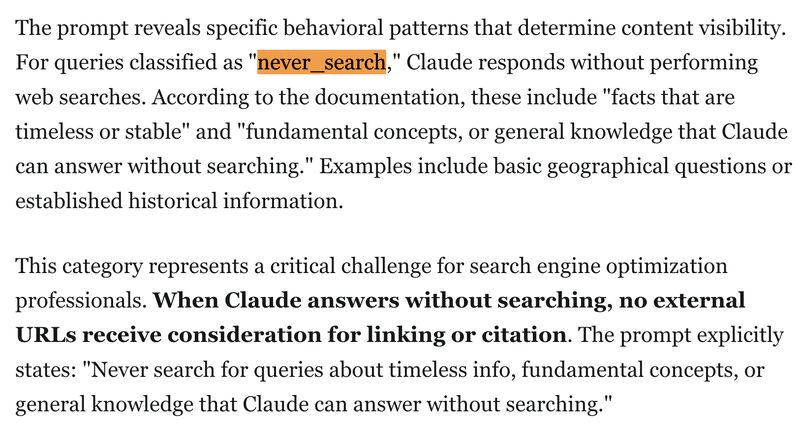
Claude answers never_search questions from training data alone, and doesn’t go looking for external URLs to cite.
Growth Advisor Gaetano DiNardi thinks other LLMs are likely following the same logic. In his words:
“the value of publishing pages on generalized knowledge is zero.”
This is the information gain problem.
Think of everything a model already knows as the overculture—the averaged-out, consensus version of a topic that’s been indexed thousands of times.
If your content only restates it, you’re redundant from the RAG framework—an AI model has nothing to gain from citing you.
What it does cite is content that adds something new: proprietary data, a named theory, a specific finding from a study, a conclusion the model can’t synthesize from its existing knowledge base.
OpenAI researcher Karthik Narasimhan published a paper on Generative Engine Optimization that offers further proof of this.
Along with peers at Princeton University, he studied which techniques are most likely to boost visibility in RAG AI systems like Perplexity.
Their findings revealed that websites featuring unique information like quotes and statistics were most commonly referenced; seeing 30-40% visibility uplift in AI responses.
| LLMO method tested | Position-adjusted word count (visibility) 👇 | Subjective impression (relevance, click potential) |
|---|---|---|
| Quotes | 27.2 | 24.7 |
| Statistics | 25.2 | 23.7 |
| Fluency | 24.7 | 21.9 |
| Citing sources | 24.6 | 21.9 |
| Technical terms | 22.7 | 21.4 |
| Easy-to-understand | 22 | 20.5 |
| Authoritative | 21.3 | 22.9 |
| Unique words | 20.5 | 20.4 |
| No optimization | 19.3 | 19.3 |
| Keyword stuffing | 17.7 | 20.2 |
Kevin Indig also found that date and number are the entity types that predict ChatGPT citations most.
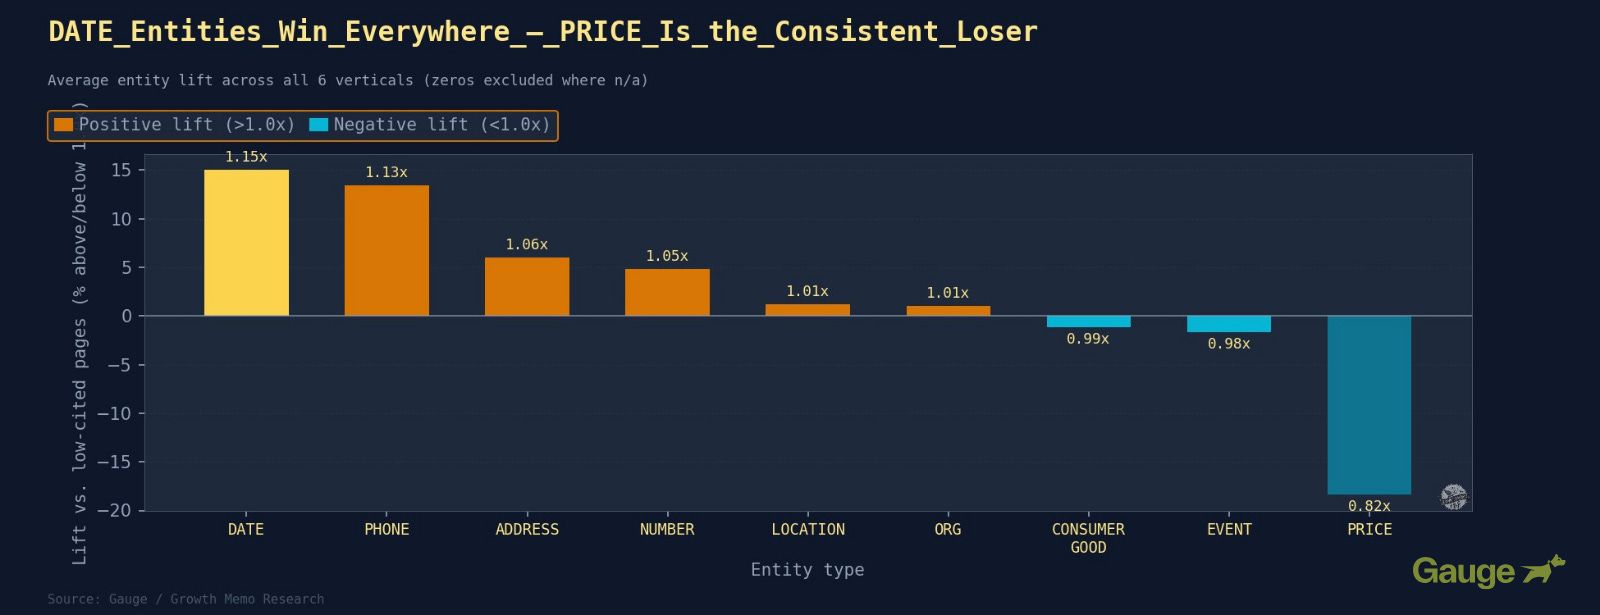
And Eric Lancheres studied 150 ranking pages and found the biggest ranking predictor was their number of unique data points.
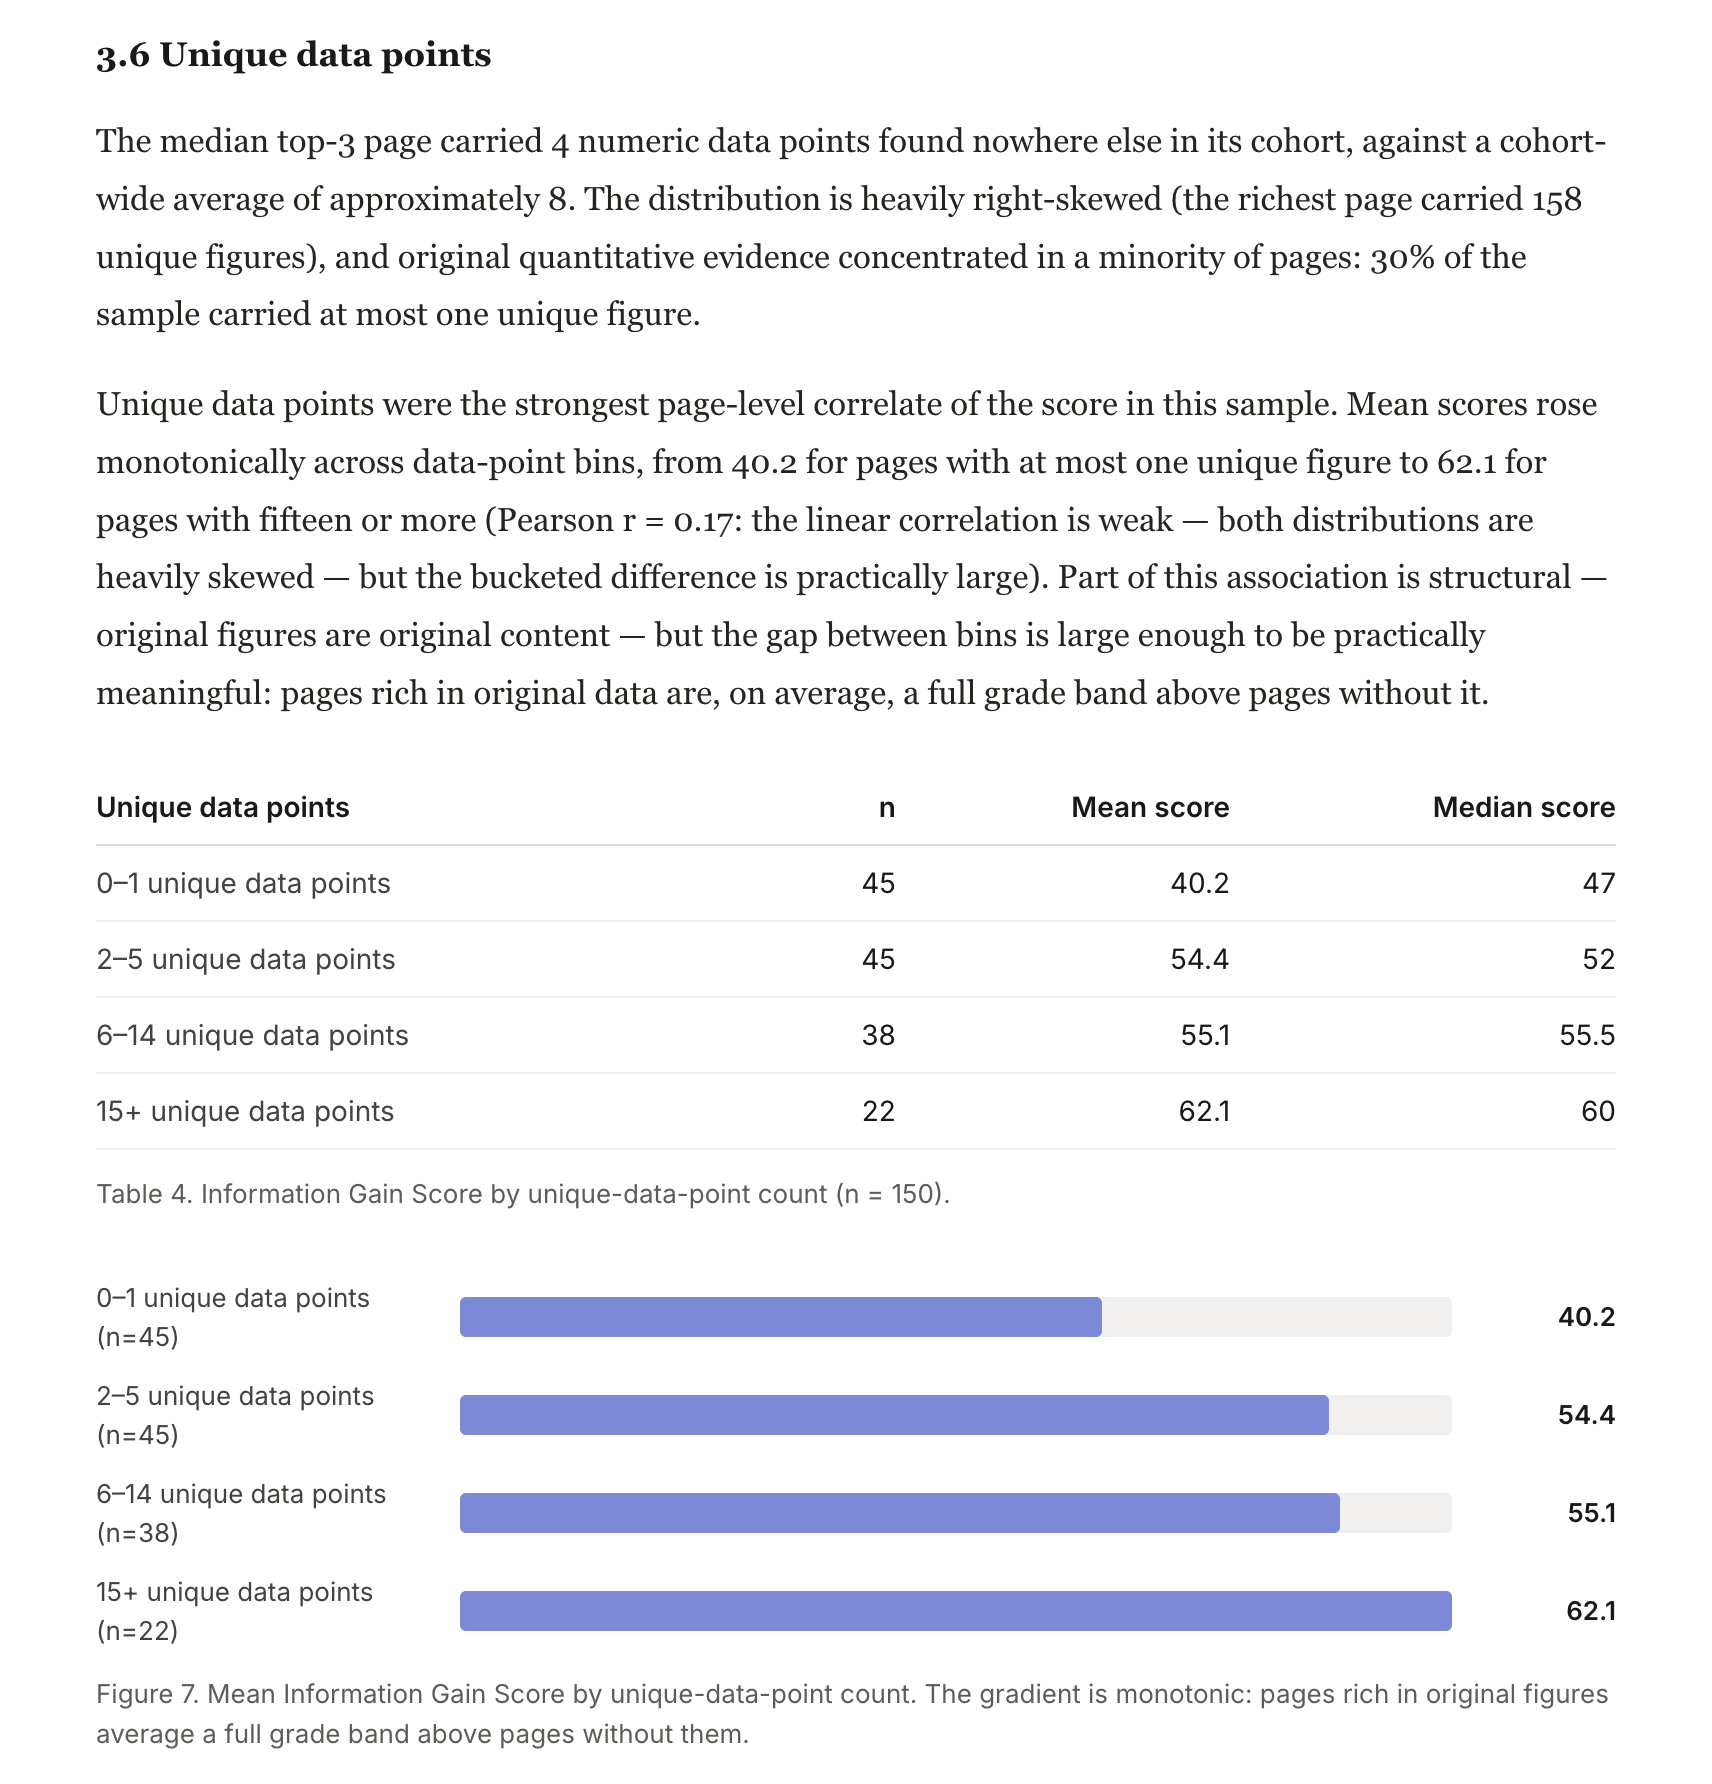
Having your content retrieved is a matter of surfacing fresh information and unique data, not chorusing what other pages have already covered.
Include a question-and-answer structure
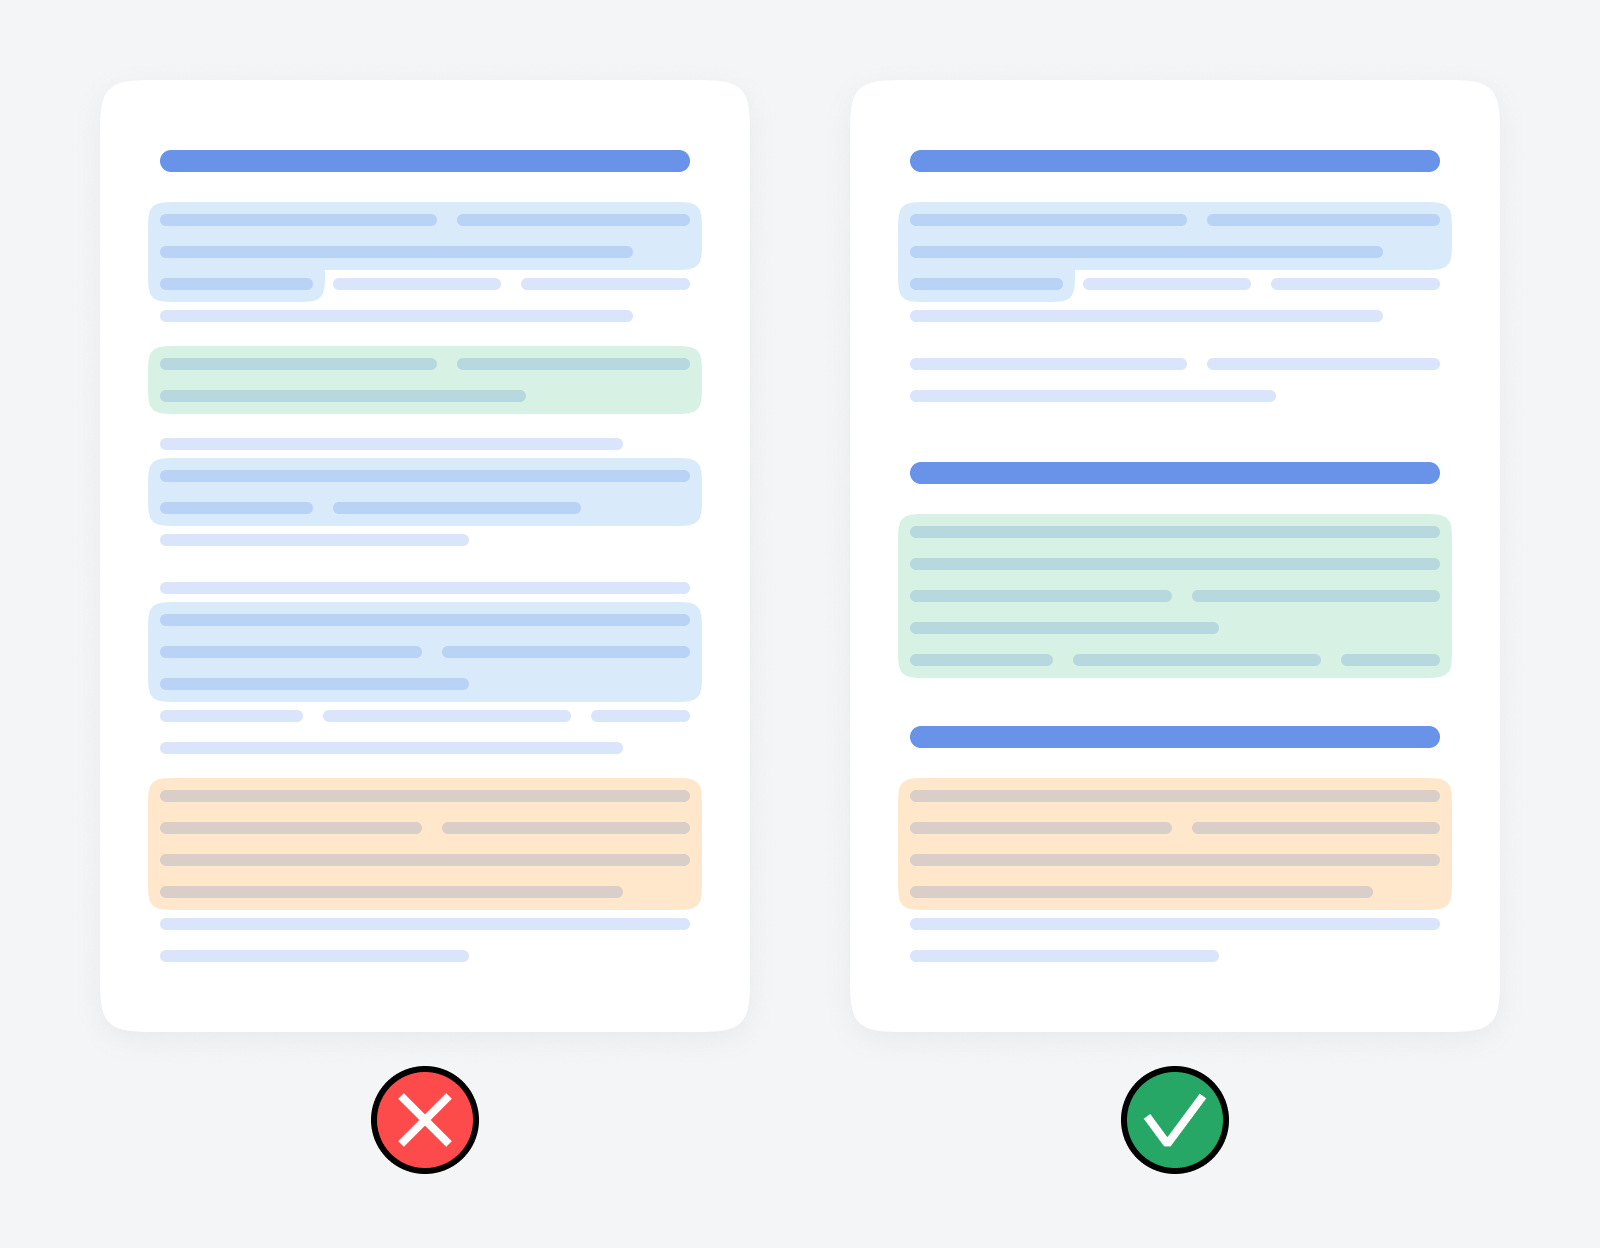
Content structured as question → immediate answer is cited twice as often as content that doesn’t follow this convention (18% vs. 8.9%), according to Kevin Indig’s data.
This is yet another example of BLUF in play.
AI models try to match user queries (almost always a question) to a chunk that answers it.
In the words of Suganthan Mohanadansan:
“Citations bind to a specific sentence, not the whole answer, so being topically relevant isn’t enough, you have to be the best support for a precise claim.”
Formatting your content as a Q&A can help AI models like ChatGPT make a direct, unambiguous match.
Mohanadasan also found that ChatGPT deduplicates results by domain, so 20 thin pages on your site don’t add up to 20 chances at citation.
ChatGPT selects the one page that best matches the user’s initial query and fan-out subqueries.
Put your strongest answer on that page, not spread across all 20.
Tip
In the words of Eli Schwartz: “The vast majority of pages get considered and rejected before the answer is ever written.”
In Brand Radar you can filter citations by “Found but not cited” to see every response where your page was pulled into ChatGPT’s retrieval set and then passed over for someone else’s.
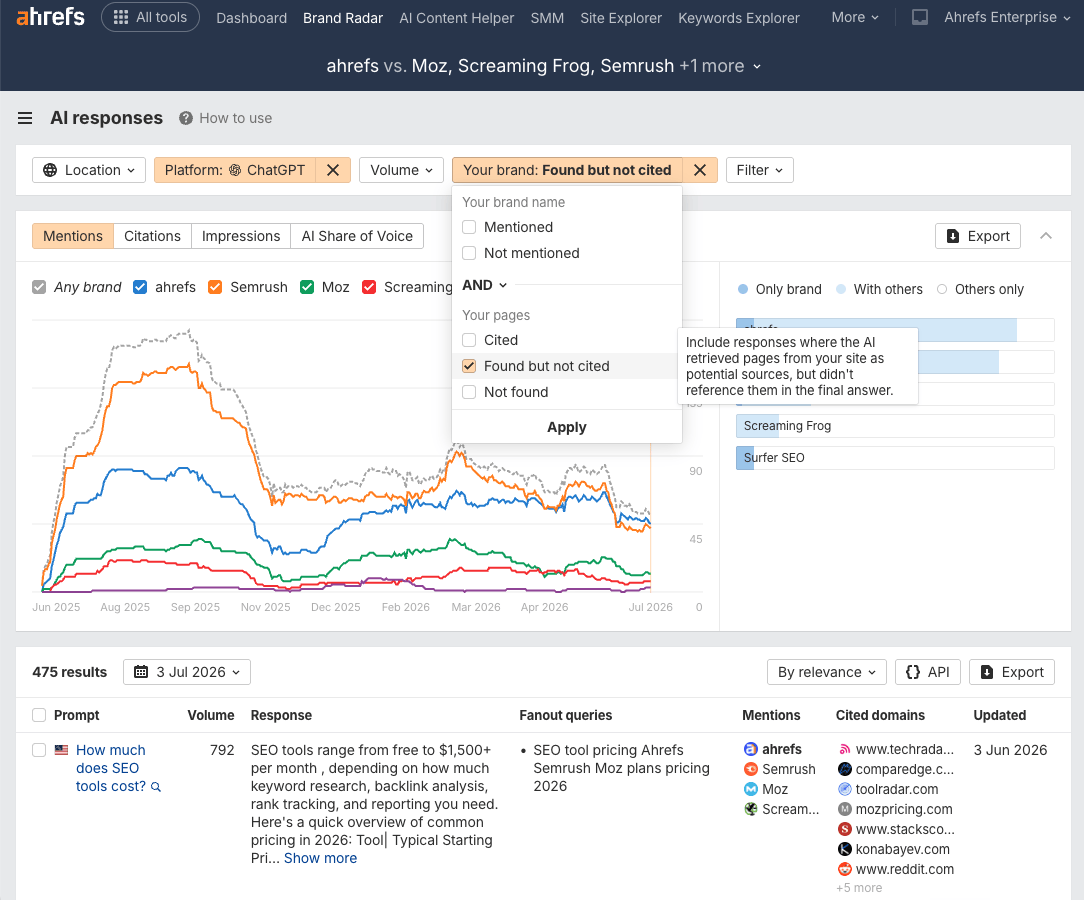
Study the pages that did get cited, and adjust your content to increase your chance of citation.
Keep content fresh
RAG search systems have a preference for current content.
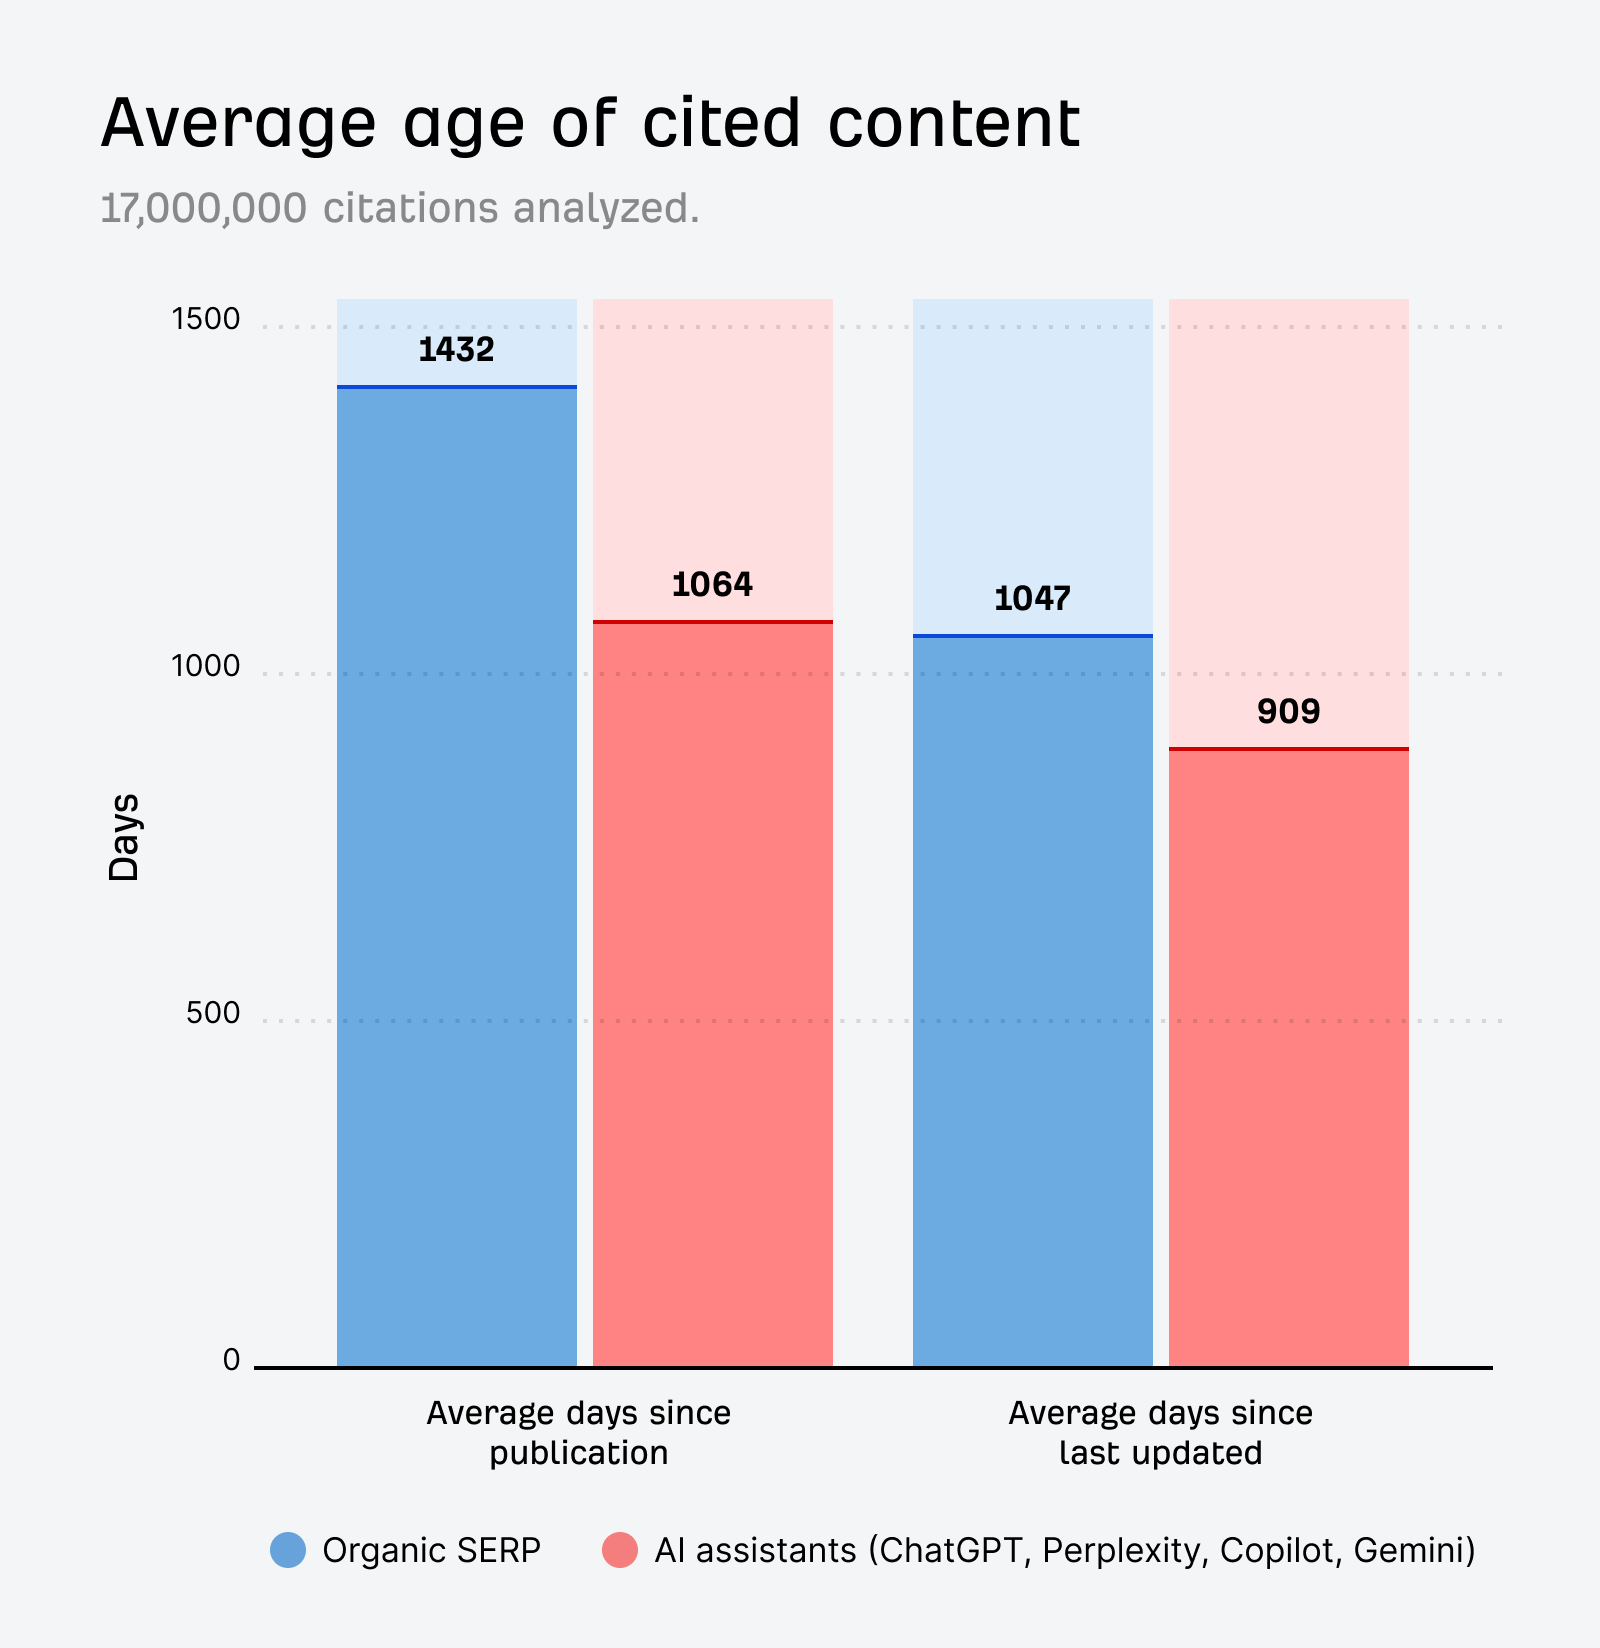
We ran a study of 17 million citations, and found that AI assistants consistently prefer to cite fresher content than search engines.
URLs cited by AI assistants are 25.7% fresher on average than URLs in standard organic SERPs—and ChatGPT and Perplexity actually order their citations from newest to oldest.
But don’t just take our word for it. Freshness is a confirmed, documented signal in AI retrieval.
Metehan Yeşilyurt’s research confirmed this. He discovered that ChatGPT has a configuration setting called use_freshness_scoring_profile: true, which bakes in a systematic recency bias.
So, your content has a much better chance of being retrieved and eventually cited if you update your key pages regularly.
Even minor updates can reset the freshness signal. Refresh statistics and examples annually and add a visible “last updated” date.
Sidenote.
One thing to remember with RAG is that AI models often retrieve cached versions of pages rather than the live page. So if you updated your content yesterday, the AI may still be reading an older version from the search index’s cache.
Further reading
Optimizing your content for RAG is vital, but you need to know if it’s working.
Ahrefs Brand Radar was built to help brands monitor their visibility in retrieval augmented AI results.
Here’s how I suggest using it to improve your visibility in RAG.
Track your baseline visibility
Before changing anything, find out where you actually stand.
Search your brand in Brand Radar to see how often you’re appearing in AI answers for your target topics, and which platforms are citing you.
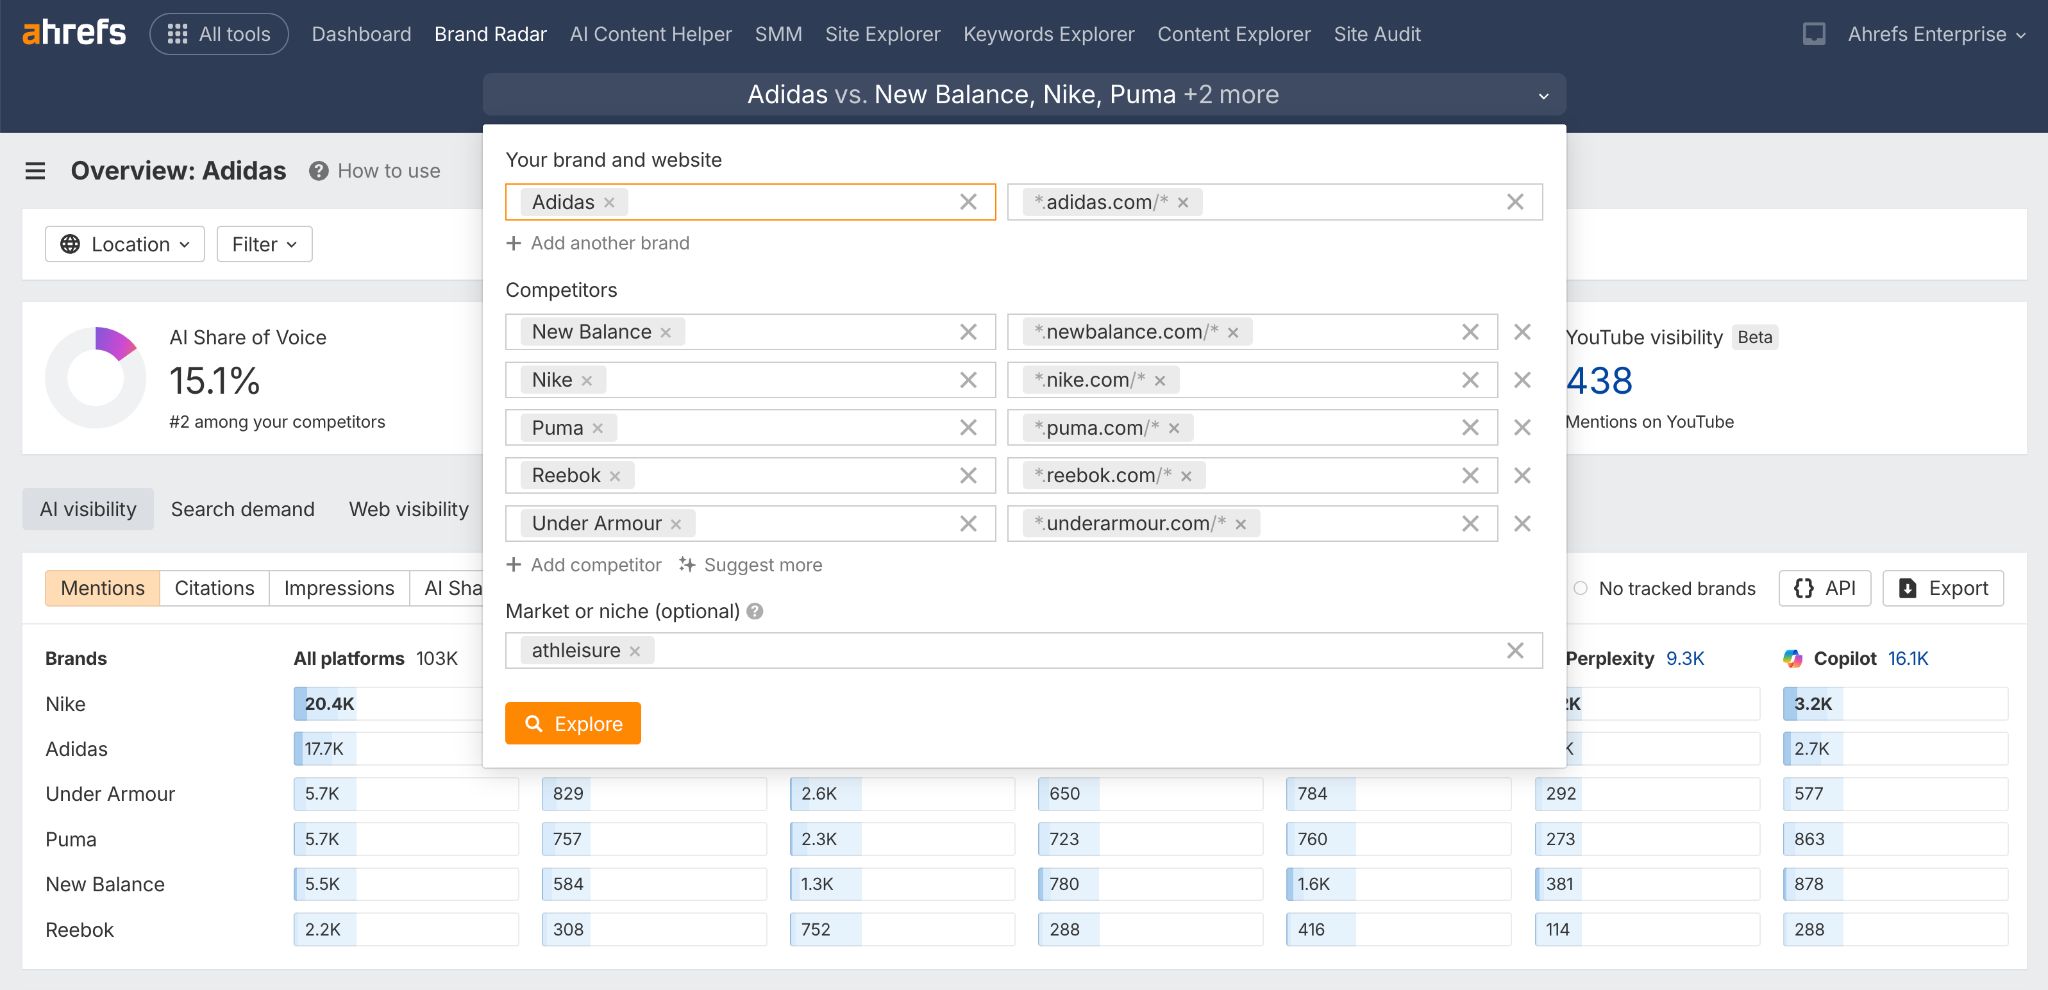
If mentions are low or absent, see who is being cited instead.
Find out which AI platforms are citing you (and which aren’t)
Different AI platforms have different retrieval architectures with different biases toward freshness, authority, and structure.
Brand Radar’s platform breakdown can reveal gaps like “AI Mode cites us regularly, but we lack visibility in Perplexity.”
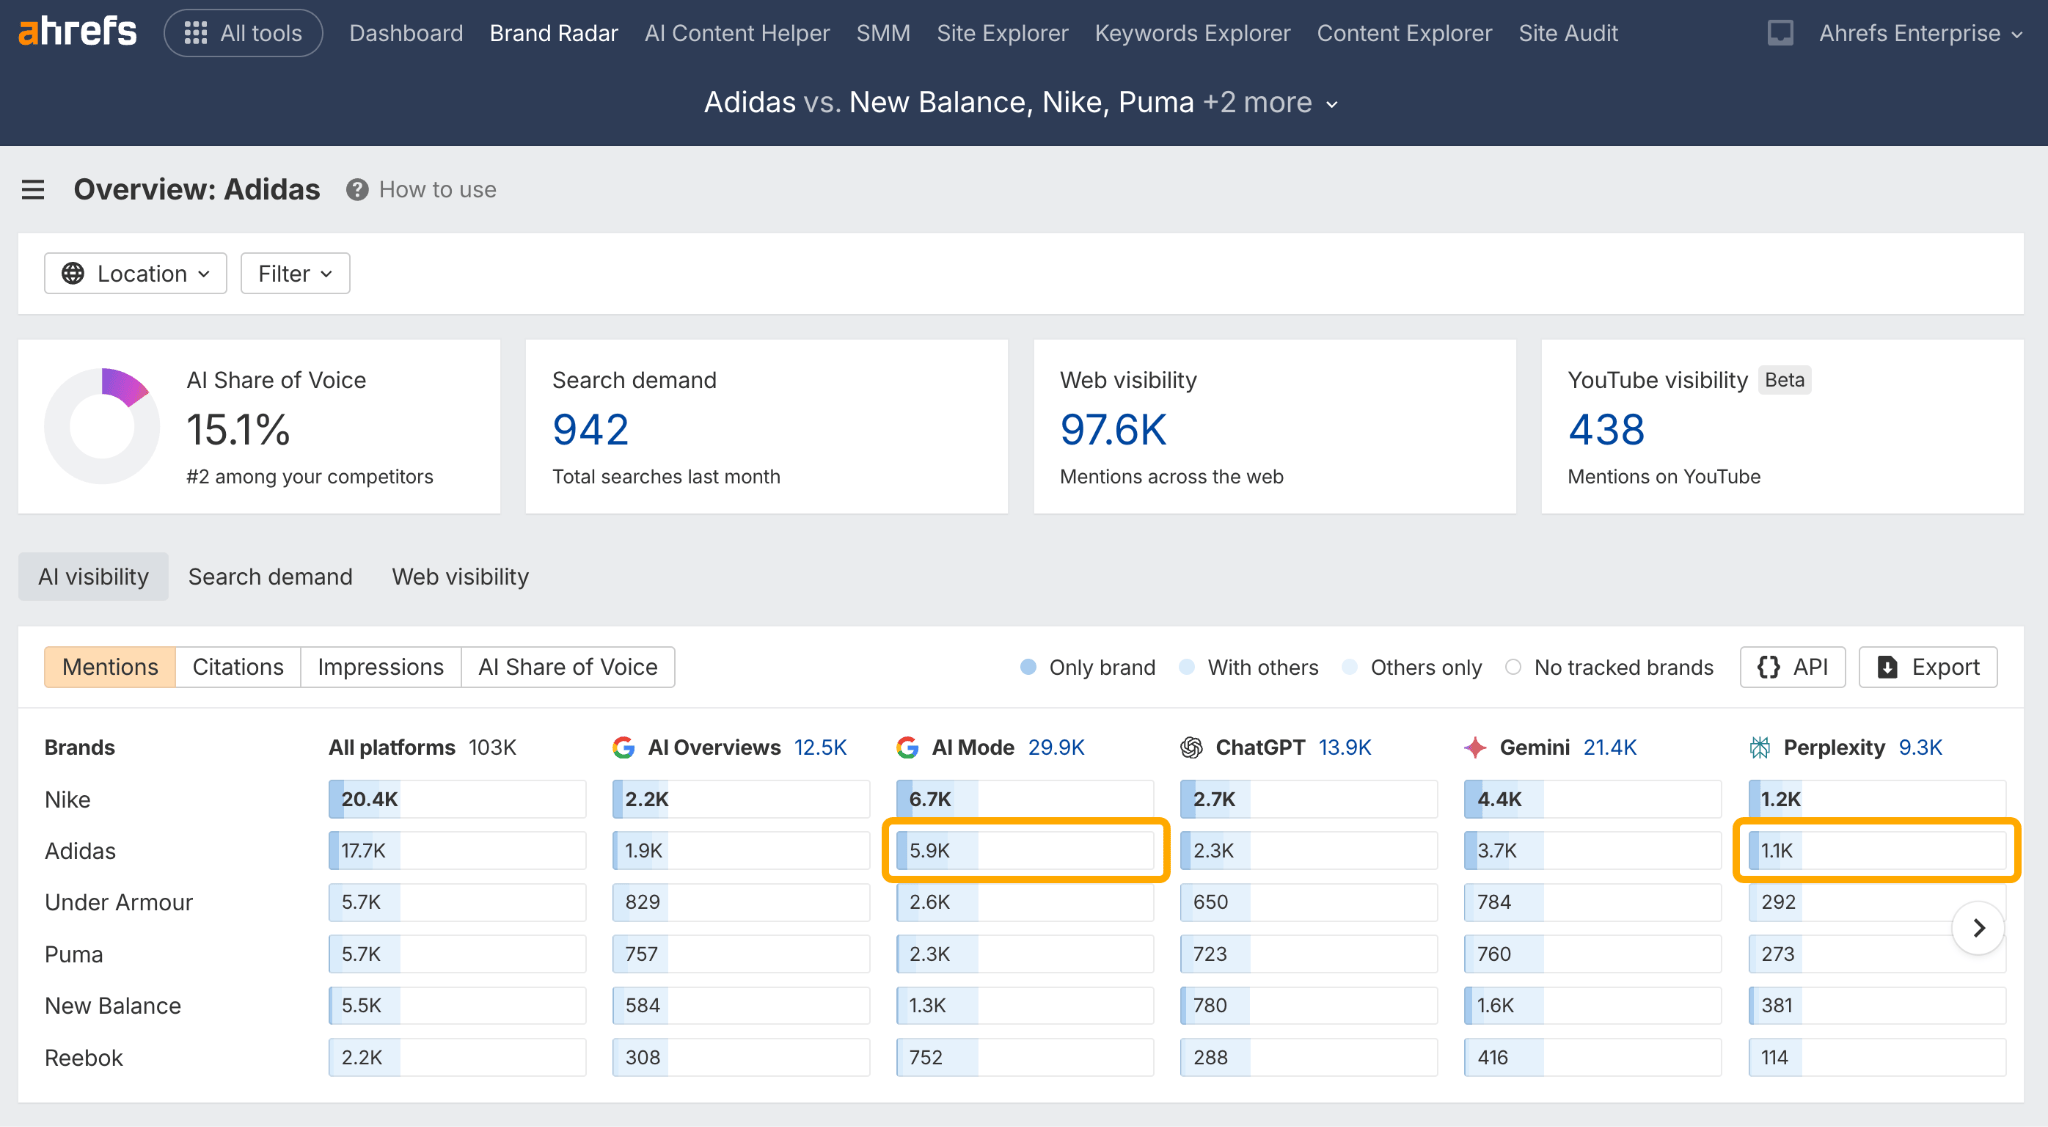
If your site performs badly on only one platform, the issue is likely with how that platform evaluates it—not the content itself.
For example, if a page ranked well on Google but not on Bing, we’d see that as a Bing-specific signal (like links, entities, or indexing) rather than the page being low quality overall—the same is true of AI visibility.
Discover which queries are triggering your citations
Seeing the exact queries that lead to citation tells you what’s working, and flags related queries where you’re not appearing yet.
Because of query fan-out, you may already be getting cited for queries you’d never have thought to target.
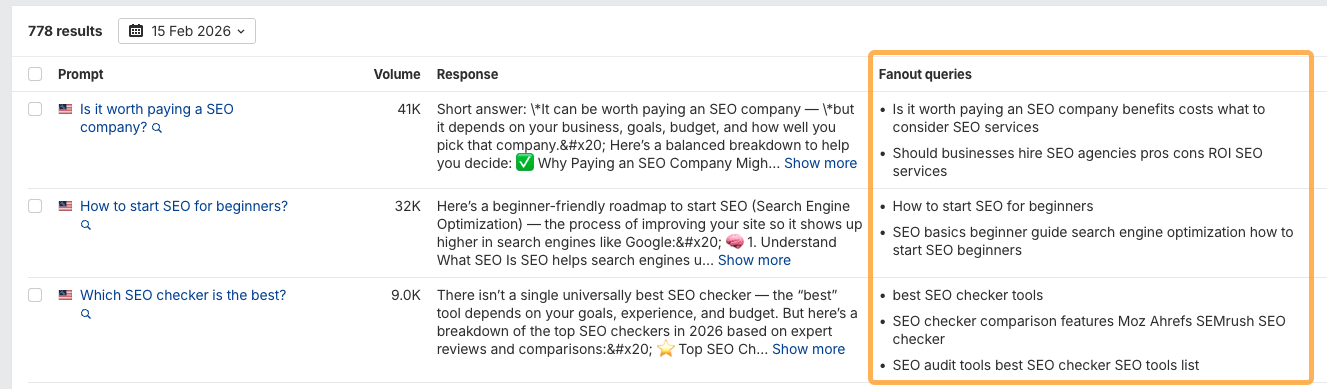
Brand Radar’s database contains millions of existing queries, meaning you can stumble on new content opportunities you wouldn’t otherwise know existed.
Track whether content updates change your citation rate
Once you’ve made changes to optimize your content for retrieval—applying BLUF, targeting fan-out queries, incorporating statistics—monitor Brand Radar to see whether your citations grow in the following weeks.
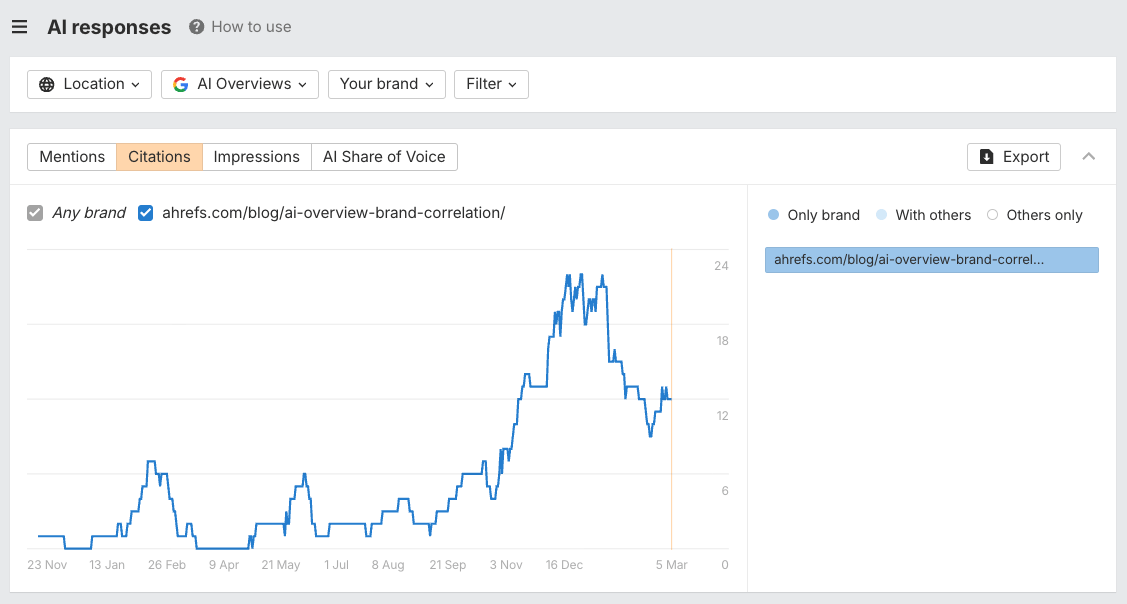
This lets you build a feedback loop: optimize → publish → measure → iterate.
The same kind of methodology that works for tracking organic rankings also applies to AI citation tracking.
Benchmark against competitors
Find out which of your competitors is being consistently cited by AI for queries you care about, then analyze the structure and content of their most-cited pages.
Just add a Your brand: Not mentioned and Your brand: Found but not cited filter to an AI Responses or Cited Pages report in Brand Radar.
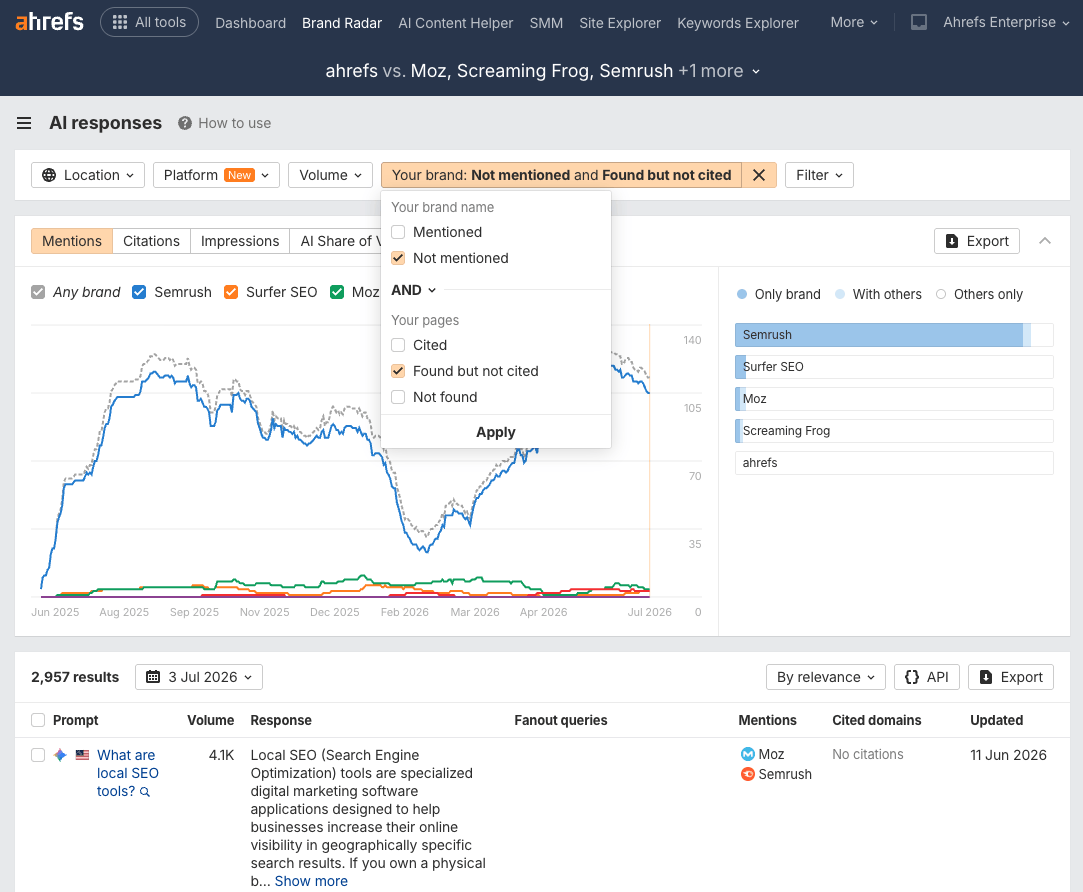
This will show you the topics and third-party discussions your brand tends to be left out of.
Then it’s just a case of reverse-engineering your competitors’ moves to close the gap.
RAG is the bridge between search and AI. It follows predictable rules, promoting pages it can access, fetch quickly, and topic-match directly to give the best possible answer.
Track your AI visibility with Ahrefs Brand Radar to see whether your content is showing up across ChatGPT, Perplexity, Google AI Overviews, and the other tools your audience actually uses.
Got questions? Ping me on LinkedIn.